/t/, /tʰ/, /ɾ/as in top
You likely produce a fully aspirated or fully released tongue-tip stop in every position, including between vowels in words like 'city' or 'water', because Mandarin syllables don't have this quick, voiced in-between…
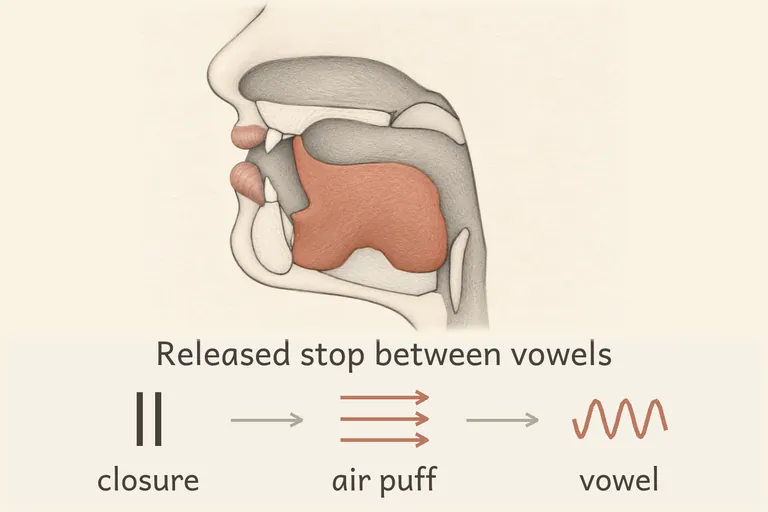
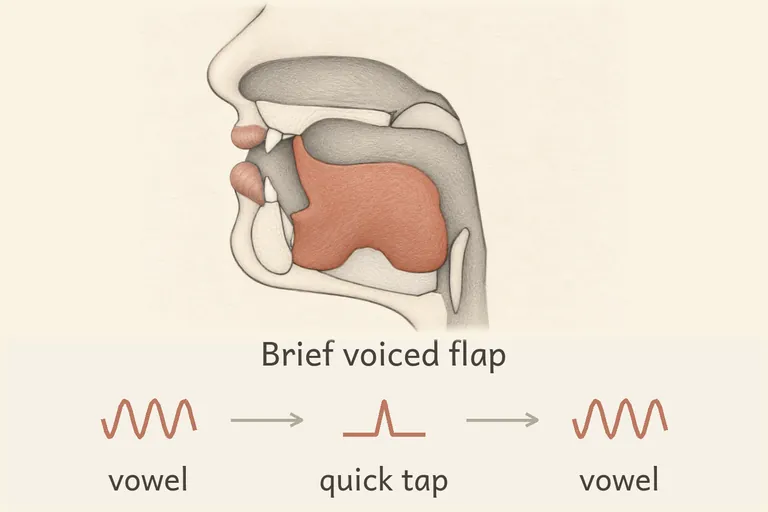
What you probably do
You likely produce a fully aspirated or fully released tongue-tip stop in every position, including between vowels in words like 'city' or 'water', because Mandarin syllables don't have this quick, voiced in-between version. At the end of words like 'bit' or 'button', you may drop the /t/ altogether or add a small vowel after it, since Mandarin doesn't allow syllables to end in oral stops.
How natives do it
Americans turn /t/ into a fast, light tongue-tap between vowels, almost like a quick 'd', so 'city' sounds closer to 'siddy'. At the end of a word they usually just hold the tongue-tip closure briefly or release it very softly, without any extra vowel or a full aspirated burst.
Why it matters
Skipping the flap makes mid-word /t/ sound stiff and overly formal, while dropping or vowel-izing final /t/ can blur distinctions like 'bit' versus 'bid'. Learning both the flap and the light final stop will make your rhythm and word endings sound much more natural.
Hear the difference
Words this touches
Mandarin Chinese speakers often substitute /t, tʰ/.
How the mouth differs
Mandarin's t/tʰ pair matches English aspirated word-initial /t/ reasonably well, but English also neutralizes /t/ to a quick voiced tap between vowels ('city', 'water') and frequently drops or glottalizes it in codas ('button', syllable-final /t/ with no following vowel). Since Mandarin never ends syllables in oral stops, learners tend to over-articulate a full, released /t/ everywhere, skipping the flap and sometimes dropping or vowel-izing final /t/.
Listen for the pattern
A fully released, crisp /t/ in words like 'better' or 'city' sounds overly formal or foreign to American ears, who expect a fast, almost /d/-like tap there; meanwhile deleting final /t/ in words like 'bit' can make it sound like 'bi' or merge with voiced-final words like 'bid'.
Practise it
Can You Hear the Difference? American T Sounds
sourced- Listen to each pair of words spoken naturally by an American speaker (use a dictionary audio clip or text-to-speech): 'writer' vs 'rider', 'latter' vs 'ladder', 'bet it' vs 'bed it'.
- For each pair, don't look at the spelling yet — just listen and guess which word you heard.
- Notice that 'writer' and 'rider' can sound almost identical, because both t and d turn into a quick tap between vowels — the real clue is the length of the vowel right before it.
- Now listen to 'top', 'stop', and 'button' and notice how differently t behaves: a strong puff of air in 'top', almost none in 'stop', and a swallowed stop before the nose sound in 'button'.
- Replay each set three times, trying to predict the pattern before you hear it.
- Write down which position in the word (start, between vowels, before a nasal) produces which version of t.
Success check: You can correctly predict whether a word's t will be puffed, plain, flapped, or swallowed just from its position in the word, and you can tell apart vowel length cues in pairs like 'writer' and 'written'.
Why this works. Trains perceptual discrimination of English /t/'s context-dependent allophones (aspirated, plain, flapped, glottalized), which do not correspond to a single uniform category the way a dental t does in some L1s. Perception errors with L2 consonants typically arise from mapping the new sound onto an existing L1 category rather than a true inability to hear the acoustic difference, so explicit discrimination practice targets the categorization problem directly before production work begins.
Sources (1)
- Distinguishing universal and language-dependent levels of speech perception: Evidence from Japanese listeners' perception of English “l” and “r” — Virginia A. Mann, 1986
- Japanese listeners successfully discriminate the acoustic properties of English /l/ and /r/ when presented with non-English contrasts, ruling out a universal hearing deficit.
- The primary source of error is language-dependent categorization, where listeners map English sounds onto their existing L1 phonological categories (e.g., classifying both as liquids).
- Performance improves significantly when the acoustic contrast between /l/ and /r/ is exaggerated or presented in contexts that highlight their distinctiveness.
Drill Sentence: All Three T's in One Breath
sourced- Read this sentence once silently: 'The waiter at the little water bar poured better butter for the writer's party.'
- Mark every t: which ones start a stressed syllable (strong puff expected) and which ones fall between vowels (flap expected).
- Say the sentence very slowly, exaggerating each t type as you go.
- Record yourself saying it at a normal conversational speed.
- Listen back and circle any t that still sounds like a uniform, fully-held stop everywhere.
- Repeat the sentence five times, smoothing out the flapped t's until they disappear into quick taps.
Success check: You hear a clear puff on 'waiter' and 'water' at the start, but fast, almost d-like taps in the middle of 'little', 'water', 'better', and 'butter'.
Why this works. Drilling a sentence loaded with all three target allophones builds automaticity for context-dependent allophone selection under connected-speech demands, which isolated word practice does not train. Training-induced gains tend to be larger when target sounds are practiced embedded in sentences rather than elicited in isolation, since sentence context forces the learner to manage allophone switching at natural speed.
Sources (1)
- Training the pronunciation of L2 vowels under different conditions: the use of non-lexical materials and masking noise. — Joan C Mora, Mireia Ortega, Ingrid Mora-Plaza et al., 2022
- Non-lexical training materials produced greater pronunciation improvements for L2 learners compared to lexical (word-based) materials.
- Masking noise during training hindered performance specifically for participants using non-lexical stimuli, but did not negatively affect those using words.
- Training-induced gains in vowel production were more pronounced when vowels appeared in sentences than when elicited in isolated words.
Exaggerate First, Then Dial It Back
sourced- Say 'top' with a huge, cartoonish puff of air after the t — almost like you're blowing out a candle.
- Say 'butter' with an extremely long, loose, floppy tap in the middle — let the tongue bounce almost in slow motion.
- Say 'button', holding the glottal stop for a full second before releasing into the n.
- Record all three exaggerated versions.
- Now say the same three words at about 70% of that exaggeration — still clearly puffed, tapped, and glottalized, but closer to normal speed.
- Finally, say them at natural conversational speed, keeping just a trace of each distinct quality.
- Compare your natural-speed recording to the exaggerated one and confirm the contrast is still audible, just subtler.
Success check: Even at normal speed, a listener can still tell 'top' has a puff, 'butter' has a tap, and 'button' has a stop-nasal release — the exaggeration training left behind a real, audible trace.
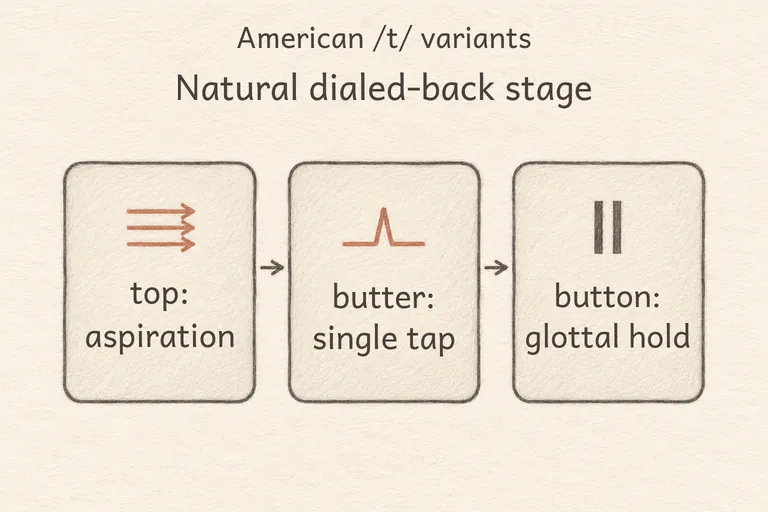
Why this works. Overshooting each allophone's defining cue (burst length, tap looseness, closure duration) before fading toward natural speed strengthens category learning more than practicing at normal speed from the start, since exaggerated training has been shown to induce more native-like categorical perception and leaves a durable trace even once the exaggeration is dialed back.
Sources (1)
- Frontiers | The Role of Temporal Acoustic Exaggeration inHigh... — 2019
- The HVPT-E group showed superior improvement in natural word identification compared to the standard HVPT group.
- Temporal acoustic exaggeration promotes native-like categorical perception based on spectral cues in adult L2 learners.
- Training with temporal exaggeration induces measurable changes in pre-attentive neural processing (MMN responses).
Produce the Three American T's
sourced- Say 'top' out loud, pushing a strong puff of air right after the t — hold a tissue in front of your mouth and watch it flutter.
- Say 'stop' the same way, but keep the t crisp with almost no puff of air, since it follows s.
- Say 'butter' slowly, then speed up until the middle t turns into a quick, light tap of the tongue tip — almost a fast American 'd'.
- Say 'button', and instead of releasing the t normally, stop the air completely and release it through your nose into the n.
- Record yourself saying all four words in a row: top, stop, butter, button.
- Play it back and check for four distinct sounds: strong puff, no puff, quick tap, swallowed stop.
- Repeat five times, exaggerating each version before settling into a natural speed.
Success check: Your recording shows four clearly different t's — a puffy one, a crisp one, a fast tap, and a nasal-released one — not four identical dental stops.
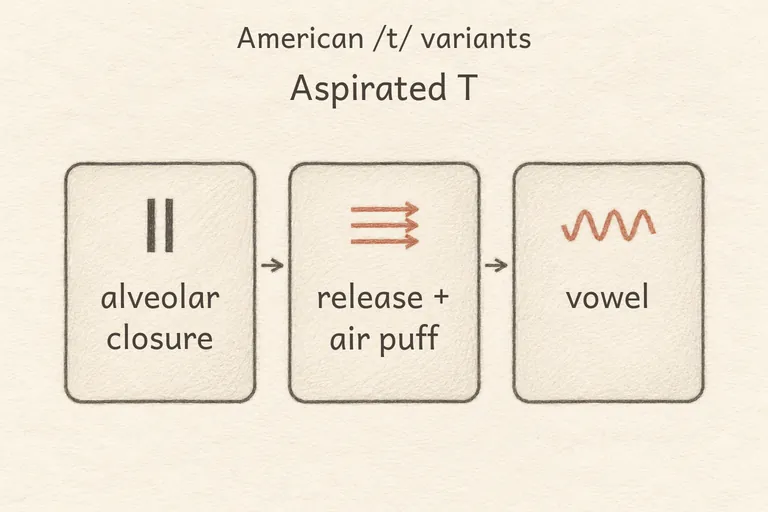
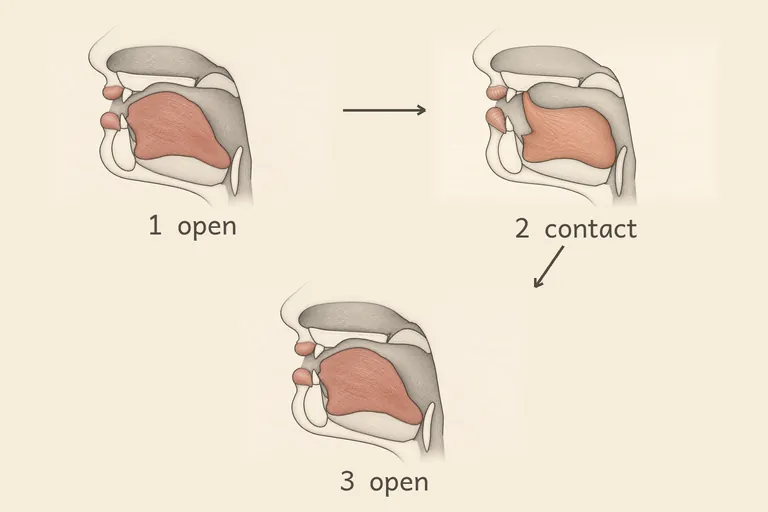
Why this works. Moves from perception to production, training the learner to generate three distinct allophones of /t/ on cue. Tracking both how correct (goodness) and how clear (intelligibility) a produced sound is gives a more complete picture of progress than accuracy judgments alone, which is especially useful here since a flapped t can sound 'wrong' in isolation yet be perfectly intelligible in context.
Sources (1)
- Using multiple measures to document change in English vowels produced by Japanese, Korean, and Spanish speakers: the case for goodness and intelligibility. — Amber D Franklin, Carol Stoel-Gammon, 2014
- Both goodness ratings and intelligibility scores effectively captured improvements in vowel accuracy following pronunciation training.
- The relationship between goodness and intelligibility varies by vowel; vowels like /æ/ and /ʌ/ depend more on goodness for listener identification than /i/ and /e/.
- Some vowels received better mean intelligibility scores but poorer mean goodness ratings after training, indicating that high intelligibility does not always require high perceived quality.
Borrow Your R-Tap to Build the T-Flap
generated- Say a word with a single-tap r, like Hungarian 'kar', and notice the quick, light touch your tongue tip makes against the ridge behind your teeth.
- Do that same tap several times in isolation, without any vowel around it — just the tap sound alone.
- Now say 'city', but instead of a full held t, replace the middle consonant with that same tap gesture.
- Compare: say the tap alone, then immediately say 'ci-TAP-y' using the identical tongue motion.
- Move on to 'butter', 'water', and 'little', using the same borrowed tap each time.
- Check in the mirror that your tongue tip barely touches the ridge and bounces right off, just like it did for your r-tap.
Success check: The middle consonant in 'butter' feels exactly like your tap-r gesture, just without any trilling, and it sounds like a fast 'd' to a listener.
Why this works. The American flap is articulatorily almost identical to a single alveolar tap, the same quick up-down tongue-tip gesture many learners already produce for a one-contact tapped r (as in Hungarian 'kar' or Spanish 'pero'). Borrowing this already-automatized tongue-tip tap and simply keeping voicing continuous, without adding a trill, lets learners access the flap through a familiar motor plan instead of building it from nothing.
Slow-Motion Steps: Building the American Flap T
consensus- Step 1 – Place: put your tongue tip lightly on the alveolar ridge, just behind your top front teeth, not touching the teeth themselves.
- Step 2 – Tap, don't hold: instead of stopping the airflow completely, let your tongue tip bounce off the ridge in one quick, light flick.
- Step 3 – Stay voiced: keep your vocal cords vibrating the whole time, so the tap sounds more like a fast 'd' than a 't'.
- Practice the tap alone, over and over, outside of any word: da-da-da-da with a very light touch.
- Insert it into 'city': say 'ci', then the tap, then 'y', very slowly at first.
- Gradually speed up 'city', 'butter', 'water', 'little' until the tap happens automatically at full speed.
Success check: At full speed, 'butter' sounds smooth and fast, with the middle consonant barely touching — closer to 'budder' than to a crisp, held 't'.
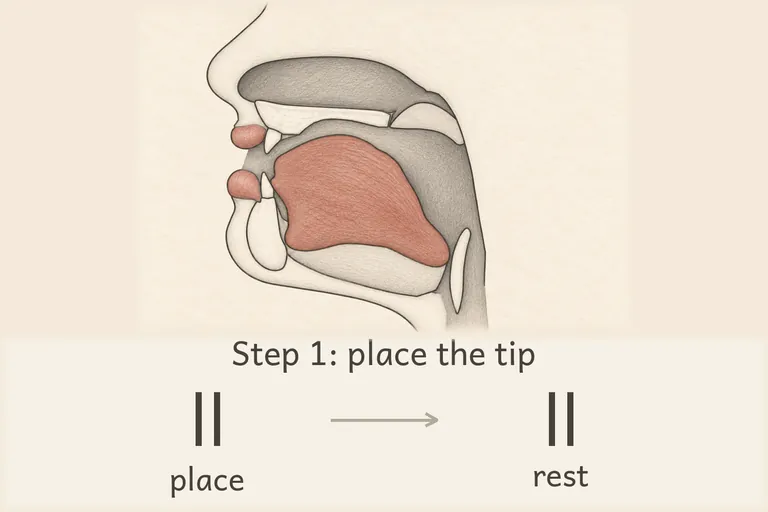
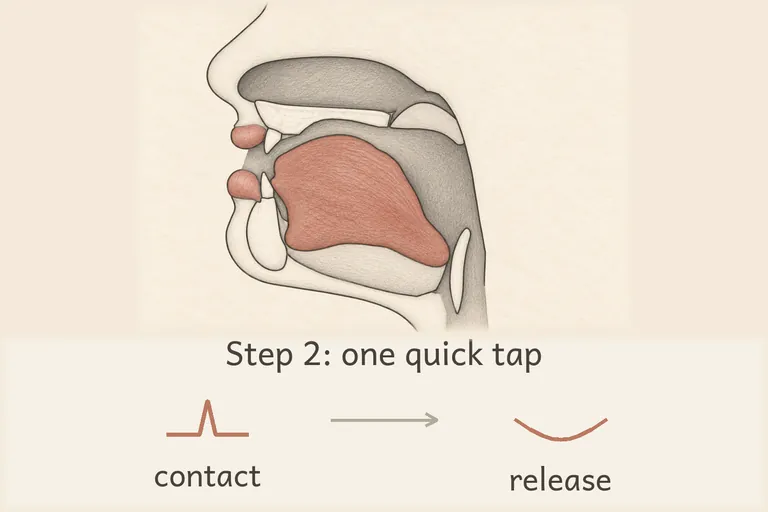
Why this works. Breaking the flap gesture into discrete motor steps (place, tap, voice) lets learners isolate the single ballistic tongue-tip movement that produces the alveolar tap, separating it from the full stop-plus-aspiration gesture typically substituted at every position.
Sources (1)
- Wells, J.C. (1982). Accents of English.
Reader ratings and feedback are coming soon.
Sources (2)
- Common Accent Features of Mandarin Chinese Speakers in English — 2026
- Mandarin speakers frequently soften or drop final consonants (e.g., 'seat' becoming 'see') because Mandarin syllables rarely end in stops.
- An extra schwa vowel (/ə/) often appears at the end of English words, creating an unnatural two-syllable rhythm where English requires a single stressed syllable.
- Consonant clusters common in English (e.g., 'texts', 'school') are simplified or omitted by Mandarin speakers due to the language's avoidance of stacked consonants.
- Wells, J.C. (1982). Accents of English.
Loads videos from YouTube via YouGlish; YouTube may set cookies.
bit in YouGlish examples