This is an AI-generated research project, still being refined. It may contain errors. Reader ratings and feedback are coming soon. How this is made
For Hindi (Modern Standard Hindi) speakers
Exercise library
66 exercises for Hindi (Modern Standard Hindi) speakers, grouped by what they train. Each one links back to
the differences it addresses.
Perception
Can You Hear the Difference? American T Sounds
sourced
minimal pair listen6 min★☆☆
Listen to each pair of words spoken naturally by an American speaker (use a dictionary audio clip or text-to-speech): 'writer' vs 'rider', 'latter' vs 'ladder', 'bet it' vs 'bed it'.
For each pair, don't look at the spelling yet — just listen and guess which word you heard.
Notice that 'writer' and 'rider' can sound almost identical, because both t and d turn into a quick tap between vowels — the real clue is the length of the vowel right before it.
Now listen to 'top', 'stop', and 'button' and notice how differently t behaves: a strong puff of air in 'top', almost none in 'stop', and a swallowed stop before the nose sound in 'button'.
Replay each set three times, trying to predict the pattern before you hear it.
Write down which position in the word (start, between vowels, before a nasal) produces which version of t.
Success check: You can correctly predict whether a word's t will be puffed, plain, flapped, or swallowed just from its position in the word, and you can tell apart vowel length cues in pairs like 'writer' and 'written'.
Why this works. Trains perceptual discrimination of English /t/'s context-dependent allophones (aspirated, plain, flapped, glottalized), which do not correspond to a single uniform category the way a dental t does in some L1s. Perception errors with L2 consonants typically arise from mapping the new sound onto an existing L1 category rather than a true inability to hear the acoustic difference, so explicit discrimination practice targets the categorization problem directly before production work begins.
Japanese listeners successfully discriminate the acoustic properties of English /l/ and /r/ when presented with non-English contrasts, ruling out a universal hearing deficit.
The primary source of error is language-dependent categorization, where listeners map English sounds onto their existing L1 phonological categories (e.g., classifying both as liquids).
Performance improves significantly when the acoustic contrast between /l/ and /r/ is exaggerated or presented in contexts that highlight their distinctiveness.
Hear the Difference: 'a' as in Cat vs. 'e' as in Bed
sourced
minimal pair listen10 min★☆☆
Gather a list of 8-10 minimal pairs like bad/bed, man/men, sat/set, pan/pen.
Have a recording, app, or partner say one word from each pair in random order.
Guess which word you heard before checking: the wider, more open word or the other one.
Check your guess immediately against the answer key.
Replay any pair you missed at least three times, focusing on how open the jaw sounds.
Repeat the full list until you score 90% or better on two rounds in a row.
Success check: You correctly identify at least 9 out of 10 words on two consecutive rounds, especially telling 'bad' apart from 'bed'.
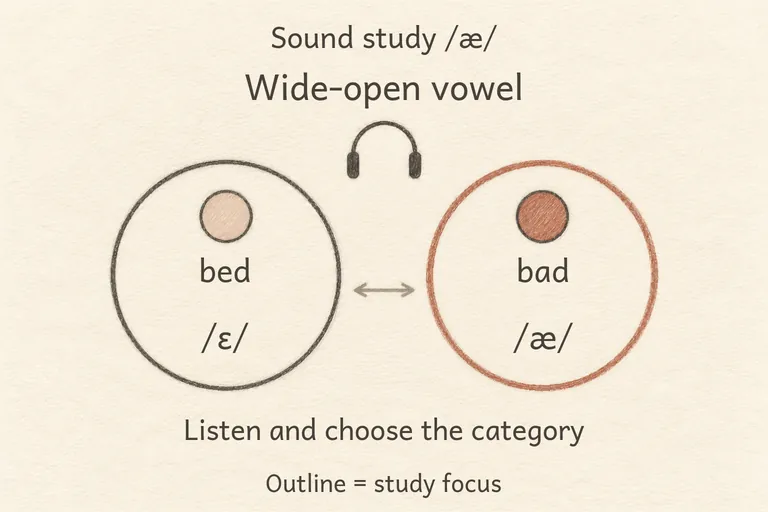
Stressed, moderately open vowelA labeled circle for the vowel in 'bed', with a moderate jaw opening.Looks almost the same as the picture.
Wide-open vowelA labeled circle for the vowel in 'bad', with a noticeably wider jaw opening.
Train your ear to notice the wider jaw opening that separates 'bad' from 'bed'.
Why this works. Forced-choice identification of æ/ɛ minimal pairs (bad/bed, man/men, sat/set) trains listeners to detect the jaw-opening cue that distinguishes the two categories. Learners whose L1 has only one open-mid front vowel (e.g., Hungarian, Spanish) tend to perceptually merge the pair, matching the L1-category-mapping pattern documented for other non-native contrasts.
Japanese listeners successfully discriminate the acoustic properties of English /l/ and /r/ when presented with non-English contrasts, ruling out a universal hearing deficit.
The primary source of error is language-dependent categorization, where listeners map English sounds onto their existing L1 phonological categories (e.g., classifying both as liquids).
Performance improves significantly when the acoustic contrast between /l/ and /r/ is exaggerated or presented in contexts that highlight their distinctiveness.
Hear the Difference: Cup vs. Cop
sourced
minimal pair listen8 min★☆☆
Put on headphones in a quiet room.
Listen to each pair — 'cup/cop', 'luck/lock' — one at a time without seeing the spelling.
Decide which word you heard: the brighter, more central vowel (cup, luck) or the darker, rounder one (cop, lock).
Check your answer, then replay any pair you missed, listening especially for lip rounding in the back vowel.
Repeat the full set of pairs three times, tracking your accuracy each round.
Stop once you can tell them apart correctly at least 9 times out of 10.
Success check: You can correctly distinguish 'cup' from 'cop' and 'luck' from 'lock' at least 9 times out of 10 by ear alone.
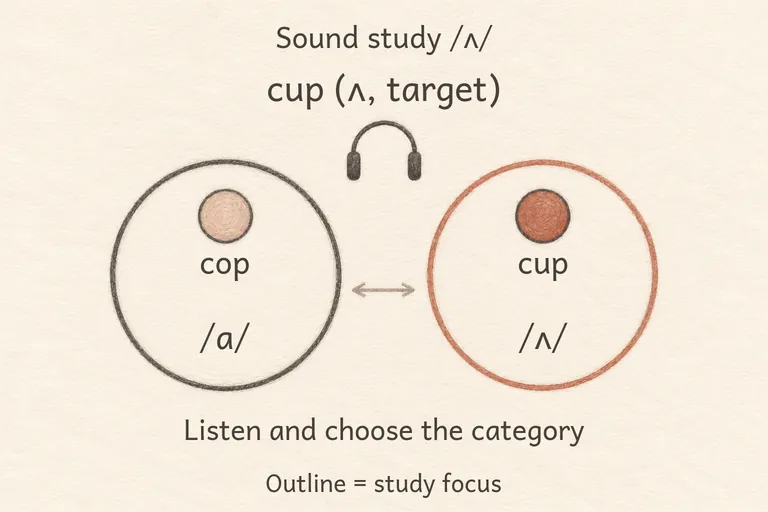
cop (back, rounded-ish)Tongue pulled back and low, lips slightly rounded, a darker-sounding vowel.Looks almost the same as the picture.
cup (ʌ, target)Tongue relaxed in the center of the mouth, lips completely unrounded, a brighter, shorter-sounding vowel.
Listen for a darker, rounder vowel in 'cop' versus a brighter, more central vowel in 'cup'.
Why this works. Forced-choice identification of 'cup/cop'-type pairs targets the specific acoustic cues (vowel backness and rounding, reflected in F2/F3 frequency) that separate central unrounded /ʌ/ from Hungarian's back rounded /ɒ/ substitute; repeated feedback-driven listening reshapes the perceptual boundary before production is attempted, following the standard perception-before-production sequence in L2 vowel training.
Both goodness ratings and intelligibility scores effectively captured improvements in vowel accuracy following pronunciation training.
The relationship between goodness and intelligibility varies by vowel; vowels like /æ/ and /ʌ/ depend more on goodness for listener identification than /i/ and /e/.
Some vowels received better mean intelligibility scores but poorer mean goodness ratings after training, indicating that high intelligibility does not always require high perceived quality.
Wells, J.C. (1982). Accents of English.
Hear the Difference: full vs fool
sourced
minimal pair listen5 min★☆☆🎙 recorder
Get a recorder or pronunciation app with audio for minimal pairs like full/fool, pull/pool, look/Luke.
Listen to the first pair twice without looking at the spelling.
Write down which word you think came first, 'full' or 'fool', before checking the answer.
Replay the pair slowly, paying attention to vowel length and lip tightness, not just the consonant.
Repeat for all three pairs, tracking how many you identify correctly on the first listen.
If you miss any, replay them three times, focusing only on how long and tense the vowel sounds.
Retest yourself once more after a short break to confirm the distinction has become clearer.
Success check: You should be able to correctly identify at least 5 of 6 pair members on a single listen, noticing the looser, shorter quality of ʊ compared to the tighter, longer u.
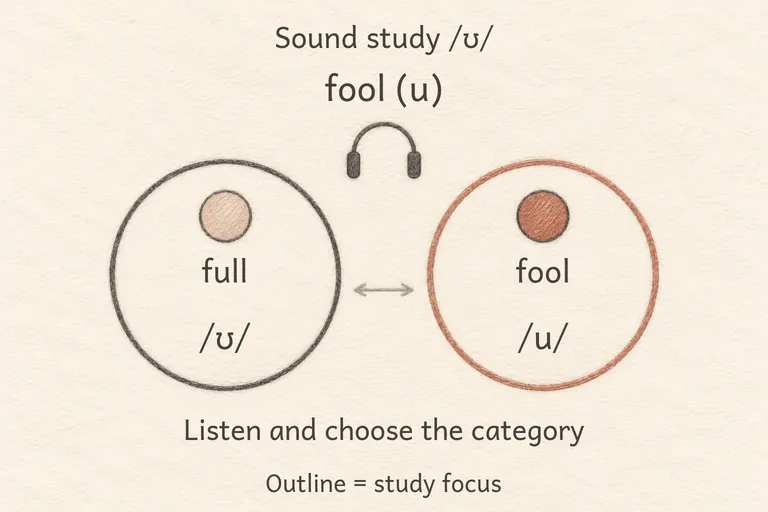
full (ʊ)Tongue relaxed, slightly lower; lips lightly rounded.Looks almost the same as the picture.
fool (u)Tongue tense and high; lips tightly rounded and pushed forward.
Listen for the looser, shorter ʊ versus the tighter, longer u.
Why this works. Discrimination training on minimal pairs isolating the tense/lax vowel contrast (u vs ʊ) builds the categorical boundary missing when the L1 has only one high back rounded vowel; contrastive discrimination training is shown to improve perceptual categorization before production gains follow.
Japanese listeners successfully discriminate the acoustic properties of English /l/ and /r/ when presented with non-English contrasts, ruling out a universal hearing deficit.
The primary source of error is language-dependent categorization, where listeners map English sounds onto their existing L1 phonological categories (e.g., classifying both as liquids).
Performance improves significantly when the acoustic contrast between /l/ and /r/ is exaggerated or presented in contexts that highlight their distinctiveness.
Both goodness ratings and intelligibility scores effectively captured improvements in vowel accuracy following pronunciation training.
The relationship between goodness and intelligibility varies by vowel; vowels like /æ/ and /ʌ/ depend more on goodness for listener identification than /i/ and /e/.
Some vowels received better mean intelligibility scores but poorer mean goodness ratings after training, indicating that high intelligibility does not always require high perceived quality.
Hear the Difference: Short 'i' vs. Long 'ee'
sourced
minimal pair listen10 min★☆☆
Write or find a list of 8-10 minimal pairs like bit/beat, sit/seat, fill/feel, chip/cheap.
Have a recording, text-to-speech tool, or a friend say one word from each pair in random order.
Before checking, guess which word you heard: the short 'i' word or the long 'ee' word.
Check your guess against the answer key right away.
For every pair you got wrong, listen to it three more times before moving on.
Repeat the whole list until you score 9 out of 10 or better on two rounds in a row.
Success check: You correctly identify at least 9 out of 10 words on two consecutive rounds without seeing the spelling.
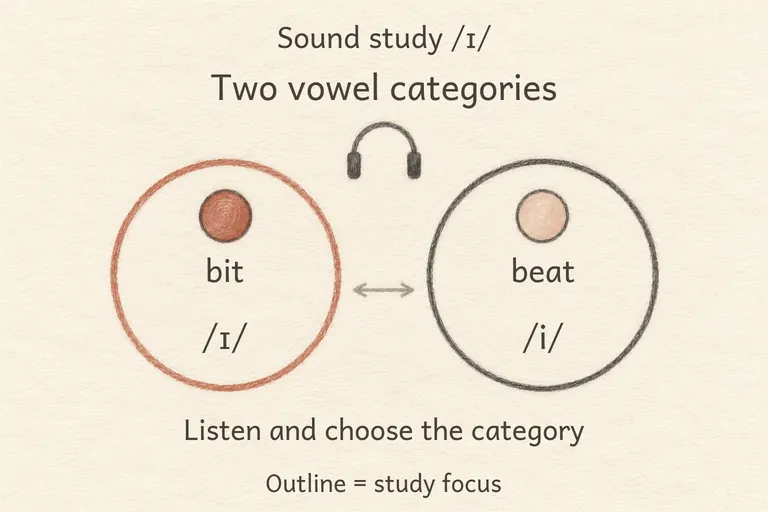
Two vowel categoriesTwo labeled circles, one for the vowel in 'bit' and one for the vowel in 'beat', with an arrow marking the boundary learners must sharpen.
Listening practice trains your ear to hear 'bit' and 'beat' as two separate sounds, not one blurred sound.
Why this works. Forced-choice identification of ɪ/i minimal pairs (bit/beat, sit/seat, fill/feel) trains listeners to attend to the tongue-height and tension cue that separates the two categories. Learners whose L1 lacks this lax/tense distinction (e.g., Hungarian, Spanish, Italian) tend to map both vowels onto one category; this mirrors the well-documented L1-category-mapping pattern seen in other non-native contrasts, and repeated feedback sharpens the perceptual boundary.
Japanese listeners successfully discriminate the acoustic properties of English /l/ and /r/ when presented with non-English contrasts, ruling out a universal hearing deficit.
The primary source of error is language-dependent categorization, where listeners map English sounds onto their existing L1 phonological categories (e.g., classifying both as liquids).
Performance improves significantly when the acoustic contrast between /l/ and /r/ is exaggerated or presented in contexts that highlight their distinctiveness.
Hear the Difference: V vs. B
sourced
minimal pair listen8 min★☆☆
Put on headphones in a quiet space.
Listen to each word pair, 'van/ban', 'vote/boat', 'very/berry', one at a time.
Before the recording reveals the answer, decide which word you heard.
Replay any pair you got wrong and listen specifically for a buzzing hum (V) versus a short popping sound (B) right before the vowel.
Repeat the full set three times, tracking your score each round.
Stop once you correctly identify at least 9 out of 10 pairs in a row.
Success check: You can correctly tell 'van' from 'ban' (and similar pairs) at least 9 times out of 10 without seeing the spelling.
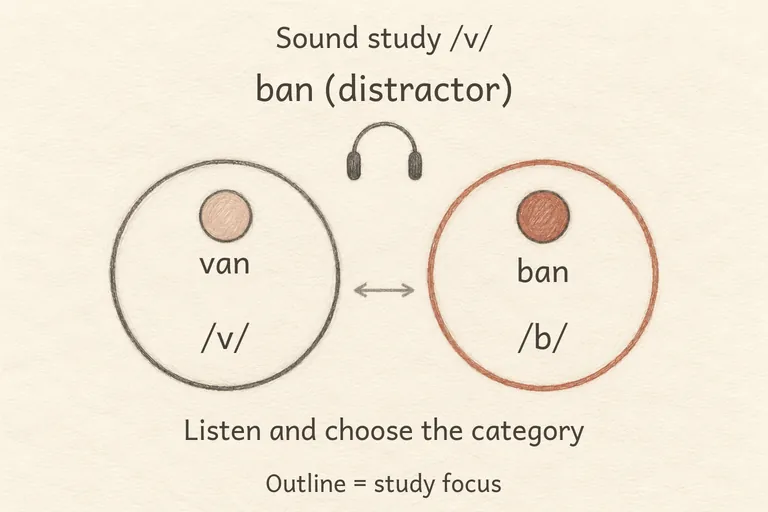
van (target)Lower lip touches the upper front teeth; a steady buzzing noise continues before the vowel starts.Looks almost the same as the picture.
ban (distractor)Both lips press together then release sharply, producing a short burst before the vowel.
Listen for a buzzing hum before the vowel (van) versus a sharp pop (ban).
Why this works. Minimal-pair listening trains categorical perception by forcing the learner to attend to the single acoustic cue that separates labiodental /v/ from bilabial /b/ — continuous frication noise with a gradual amplitude onset versus the sharp stop-burst of /b/. Because Spanish treats these as variants of one category, repeated forced-choice identification reshapes the learner's phonemic boundary, a process documented for other L1-categorization mismatches such as Japanese /l/–/r/.
Substitution occurs when learners replace L2 phonemes with the closest available sound in their native language, often causing meaning changes (e.g., Spanish /v/ becoming /b/).
Omission involves dropping sounds that do not exist in the learner's L1 or are difficult to articulate due to L1 constraints.
Insertion (epenthesis) happens when learners add vowels to break up consonant clusters that their native language does not support.
Japanese listeners successfully discriminate the acoustic properties of English /l/ and /r/ when presented with non-English contrasts, ruling out a universal hearing deficit.
The primary source of error is language-dependent categorization, where listeners map English sounds onto their existing L1 phonological categories (e.g., classifying both as liquids).
Performance improves significantly when the acoustic contrast between /l/ and /r/ is exaggerated or presented in contexts that highlight their distinctiveness.
Hear the fused r-vowel
sourced
minimal pair listen6 min★☆☆
Get pairs like bird/bud and third/thud, said aloud in random order.
Listen with your eyes closed — don't try to say anything yet.
Decide: did that word have the long, curled 'er' sound, or a plain, flat vowel?
Check your guess against the answer key.
Replay any pair you got wrong at least three times.
Notice that the curled version sounds like one long, continuous sound, not a vowel followed by a separate consonant.
Repeat until you score at least 9 out of 10 correct twice in a row.
Success check: You can reliably tell the curled 'er' vowel from a plain vowel by ear, even without watching anyone's mouth.
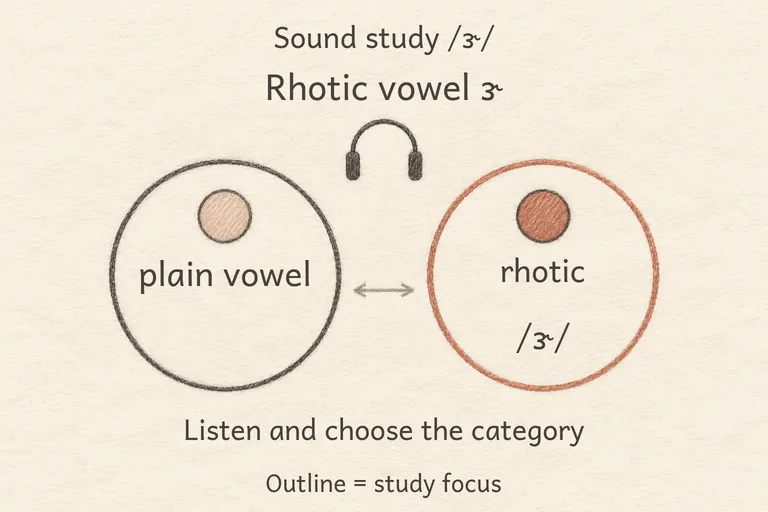
Plain vowelTongue stays low and central for the whole vowel, no curling.Looks almost the same as the picture.
Rhotic vowel ɝTongue curls or bunches upward through the entire vowel, coloring it continuously.
Listen for one long, curled sound versus a plain, flat vowel.
Why this works. Because Hungarian has no rhotic vowel, learners must build a wholly new perceptual category for the fused r-colored vowel rather than a vowel-plus-consonant sequence. Forced-choice discrimination against a plain vowel (bird/bud) trains the ear to detect the continuous r-coloring as part of the vowel itself, the necessary first step before attempting production.
Both goodness ratings and intelligibility scores effectively captured improvements in vowel accuracy following pronunciation training.
The relationship between goodness and intelligibility varies by vowel; vowels like /æ/ and /ʌ/ depend more on goodness for listener identification than /i/ and /e/.
Some vowels received better mean intelligibility scores but poorer mean goodness ratings after training, indicating that high intelligibility does not always require high perceived quality.
Hear the Glide vs. the Flat Vowel
sourced
minimal pair listen6 min★☆☆🎙 recorder
Play the recording of 'bait' and 'bet' back to back, several times.
Close your eyes and just listen for whether the vowel glides upward or stays flat.
Write down 'A' or 'B' as you hear each word in a shuffled sequence of the pair.
Check your answers against the answer key.
Repeat the same listening task with 'wait/wet', 'late/let', and 'mate/met'.
Note any pair where you consistently guess wrong, and replay it five extra times.
Success check: You can correctly identify at least 8 out of 10 shuffled words across the four minimal pairs without seeing the spelling.
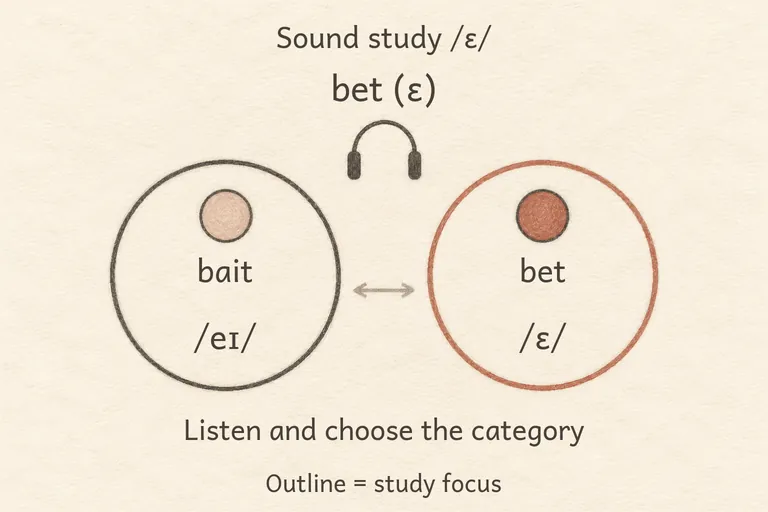
bait (eɪ)Tongue starting mid-high and gliding slightly upward toward the end.Looks almost the same as the picture.
bet (ɛ)Tongue staying lower throughout with no glide.
Listen for whether the vowel glides upward (bait) or stays flat and lower (bet).
Why this works. Repeated AX/ABX listening on pairs that differ only in vowel height and glide presence trains perceptual categorization along the one acoustic dimension that gets collapsed, strengthening the learner's internal category boundary before production practice begins.
Both goodness ratings and intelligibility scores effectively captured improvements in vowel accuracy following pronunciation training.
The relationship between goodness and intelligibility varies by vowel; vowels like /æ/ and /ʌ/ depend more on goodness for listener identification than /i/ and /e/.
Some vowels received better mean intelligibility scores but poorer mean goodness ratings after training, indicating that high intelligibility does not always require high perceived quality.
Tell Then from Den
sourced
minimal pair listen5 min★☆☆
Listen to pairs of words: then/den, though/dough, breathe/breed.
For each pair, decide whether the key sound is a soft buzzing hiss (ð) or a harder stop/sibilant (d, z).
Say 'A' or 'B' out loud, or write it down, for each pair you hear.
Check your answers against the answer key.
Replay any pair you missed three times, listening only to that one consonant.
Redo the whole set until you score at least 9 out of 10.
Success check: You can reliably distinguish ð from d/z even in random order, without needing to see the spelling.
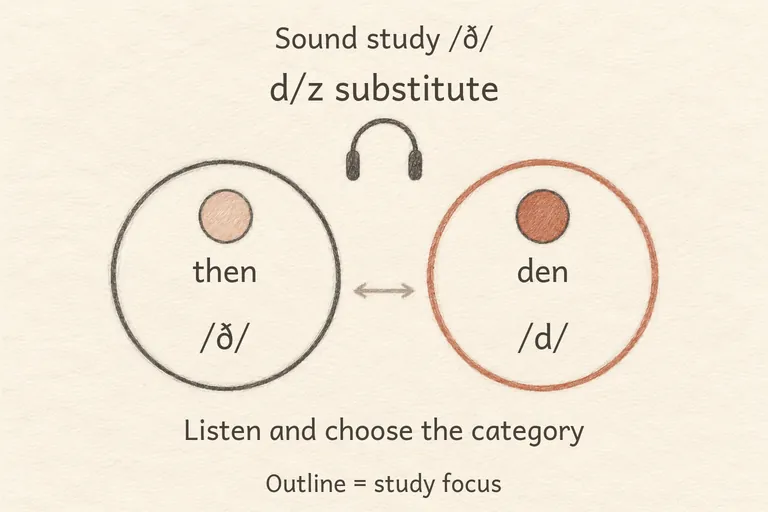
ð targetTongue tip visible between the teeth, continuous voiced buzz.Looks almost the same as the picture.
d/z substituteTongue tip retracted behind the teeth, a full stop or a sharper sibilant buzz.
Listen for the softer, continuous buzz of ð versus the harder 'd' stop or 'z' hiss.
Why this works. Presenting minimal pairs like then/den and though/dough in randomized order trains the learner's phonemic decision boundary between the voiced dental fricative ð and the d/z/v sounds Hungarian substitutes for it; sharpening perceptual discrimination first improves self-monitoring accuracy during later production practice.
Japanese listeners successfully discriminate the acoustic properties of English /l/ and /r/ when presented with non-English contrasts, ruling out a universal hearing deficit.
The primary source of error is language-dependent categorization, where listeners map English sounds onto their existing L1 phonological categories (e.g., classifying both as liquids).
Performance improves significantly when the acoustic contrast between /l/ and /r/ is exaggerated or presented in contexts that highlight their distinctiveness.
Tell Think from Sink
sourced
minimal pair listen5 min★☆☆
Listen to pairs of words: think/sink, thank/tank, bath/bat, mouth/mouse.
For each pair, decide which word you heard, 'A' or 'B'.
Focus on the key sound: is there a soft, breathy hiss (θ) or a sharper 's' hiss or a hard 't' tap?
Check your answers against the answer key.
Replay any pair you got wrong three times, paying attention only to that one consonant.
Redo the whole set until you score at least 9 out of 10 correct.
Success check: You can consistently tell θ words apart from their t/s-substituted twins without seeing the spelling, even in random order.
θ targetTongue tip visible between the teeth, steady voiceless hiss.Looks almost the same as the picture.
t/s substituteTongue tip retracted behind the teeth, either a sharp stop or a sibilant hiss.
Listen for the softer, breathier hiss of θ versus the sharper 't' tap or 's' hiss.
Why this works. Presenting minimal pairs like think/sink and thank/tank in randomized order trains the learner's phonemic decision boundary between the dental fricative θ and the alveolar sounds t/s that Hungarian substitutes for it; sharpening perceptual discrimination first improves the accuracy of self-monitoring during later production practice.
Japanese listeners successfully discriminate the acoustic properties of English /l/ and /r/ when presented with non-English contrasts, ruling out a universal hearing deficit.
The primary source of error is language-dependent categorization, where listeners map English sounds onto their existing L1 phonological categories (e.g., classifying both as liquids).
Performance improves significantly when the acoustic contrast between /l/ and /r/ is exaggerated or presented in contexts that highlight their distinctiveness.
Hear the Stress Shift: Noun vs. Verb
sourced
minimal pair listen10 min★★☆
Gather 6-8 stress-shifting word pairs like OBject/obJECT, CONvict/conVICT, PERmit/perMIT.
Have a recording, app, or partner say one version of each pair in random order.
Guess whether the word is the noun (stress on the first syllable, full vowel) or the verb (stress on the second syllable, first syllable reduced).
Check your guess immediately against the answer key.
Replay any pair you missed, listening specifically for which syllable sounds quick and neutral versus full and clear.
Repeat the set until you score 90% or better on two rounds in a row.
Success check: You can reliably tell the noun form from the verb form by ear, based on which syllable is reduced to a quick, neutral schwa.
Stressed, full vowelThe stressed syllable keeps a clear, full vowel quality, as in the first syllable of the noun 'OBject'.
Unstressed, reduced to schwaThe unstressed syllable collapses to a quick, neutral schwa, as in the second syllable of the verb 'obJECT'.
Listen for which syllable keeps a full vowel and which one collapses into a quick, neutral schwa.
Why this works. Using stress-shifting minimal pairs (object noun vs. verb, convict noun vs. verb) trains listeners to attend to the schwa-reduction cue that marks unstressed syllables in English, a feature absent from languages that keep full vowel quality regardless of stress. Correctly perceiving the reduced vowel is a prerequisite for producing natural English rhythm, and this mirrors the general L1-category-mapping pattern documented for other non-native contrasts.
Japanese listeners successfully discriminate the acoustic properties of English /l/ and /r/ when presented with non-English contrasts, ruling out a universal hearing deficit.
The primary source of error is language-dependent categorization, where listeners map English sounds onto their existing L1 phonological categories (e.g., classifying both as liquids).
Performance improves significantly when the acoustic contrast between /l/ and /r/ is exaggerated or presented in contexts that highlight their distinctiveness.
Production
Build ð One Step at a Time
consensus
slow motion steps5 min★☆☆🪞 mirror
Relax your jaw and let your mouth open slightly.
Slowly stick your tongue tip out between your teeth, same as for θ, and pause.
Turn on your voice — hum gently — while keeping the tongue tip in that same spot.
Let a light, steady buzz flow over your tongue tip along with a small stream of air.
Hold that voiced buzz for two full seconds.
Slowly pull your tongue back behind your teeth while the buzz fades.
Repeat all the steps slightly faster until it feels like one smooth motion.
Attach it to the start of 'this': hold the ð briefly, then finish the word.
Success check: You should feel your throat vibrating while your tongue tip is between your teeth, producing a soft buzz rather than a silent hiss or a stop.
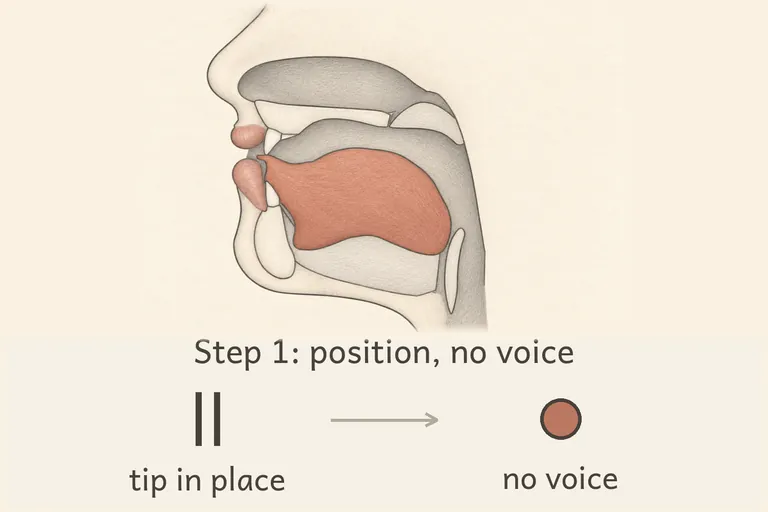
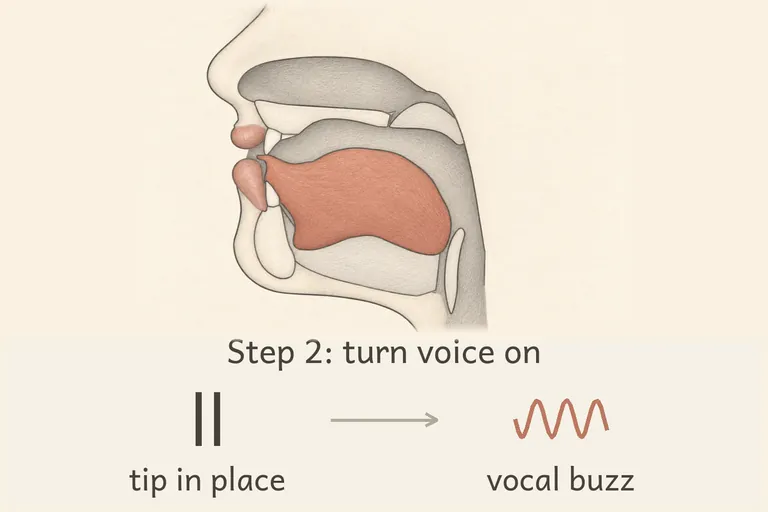
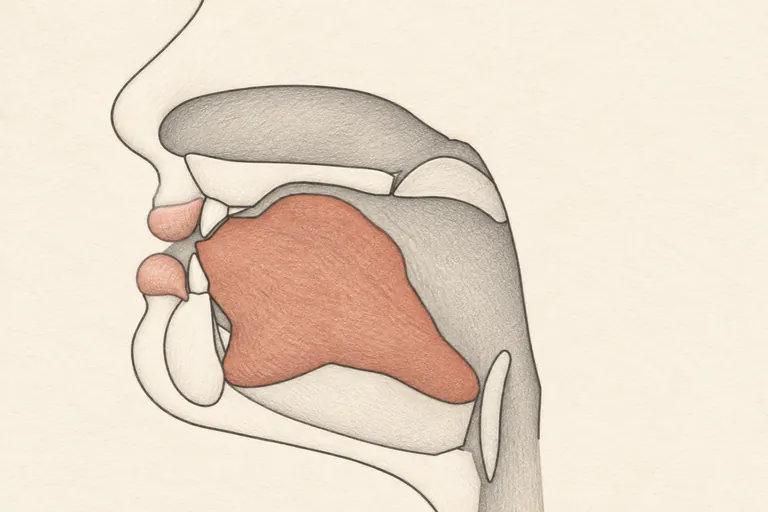
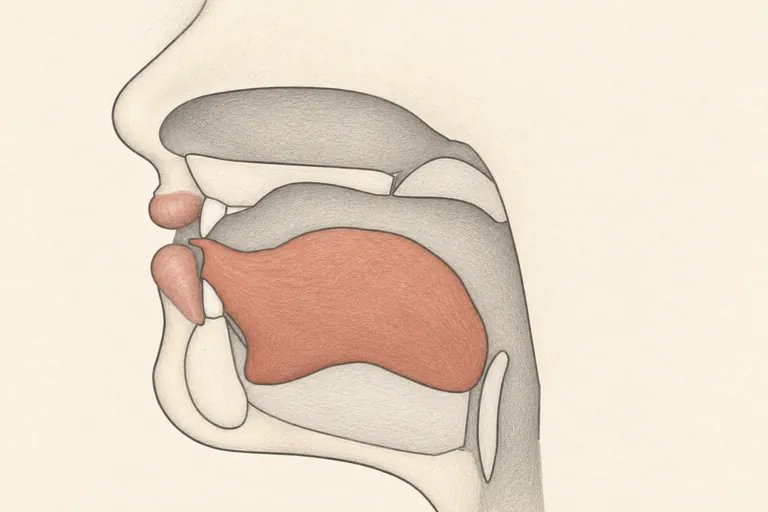
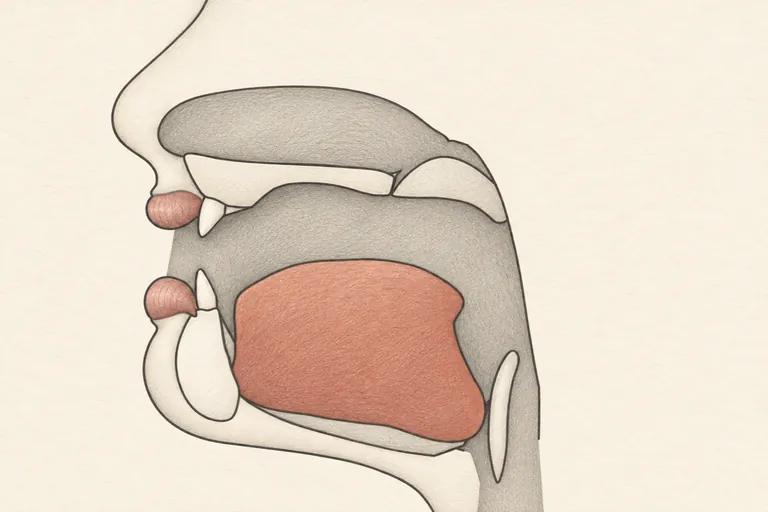
Step 1Tongue tip protrudes between the teeth, no voicing yet.
Step 2Voice turns on, a steady buzz flows over the tongue tip.
Step 3Tongue retracts as the buzz fades out.
Build ð step by step: protrude, turn on the buzz, hold, retract.
Why this works. Building the gesture step by step — protrusion, then adding continuous voicing, then retraction — lets the learner isolate the one component (vocal fold vibration) that turns the already-practiced θ gesture into ð, before reassembling the whole motion at normal speed.
Ladefoged, P. & Johnson, K. (2015). A Course in Phonetics.
Build θ One Step at a Time
consensus
slow motion steps5 min★☆☆🪞 mirror
Open your mouth slightly and relax your jaw.
Slowly stick your tongue tip out just past your upper front teeth — pause here for a second.
Let your upper teeth rest lightly on top of the tongue tip, no pressure.
Blow a slow, steady stream of air over the tongue tip; listen for a soft hiss with no voicing.
Hold that hiss for two full seconds.
Slowly pull your tongue back behind your teeth as the airflow fades out.
Now repeat all the steps slightly faster, until it feels like one smooth motion.
Attach the sound to the start of 'think': hold the θ for a beat, then finish the word normally.
Success check: You can feel your tongue tip touch or nearly touch your teeth and hear a clean, voiceless hiss before you ever add a vowel.
Step 1Jaw relaxed, mouth slightly open.
Step 2Tongue tip slides forward and pokes out between the teeth.
Step 3Steady voiceless airflow hisses over the tongue tip.
Build θ step by step: relax, protrude, hiss, retract.
Why this works. Slowing the gesture into discrete steps — jaw drop, tongue protrusion, steady airflow, retraction — lets the learner consciously control each phase of an articulation with no counterpart in Hungarian, before reassembling it at normal speed into a single automatic motion.
Ladefoged, P. & Johnson, K. (2015). A Course in Phonetics.
Exaggerate, then Dial Back: Finding True ɛ
sourced
exaggeration4 min★☆☆🪞 mirror
Say the word 'bet' with your normal, higher tongue position and notice how it feels.
Now open your jaw much wider than feels natural and drop your tongue very low, saying 'bet' again in an exaggerated, almost silly way.
Repeat the exaggerated version three times, feeling the big difference from your habitual position.
Gradually reduce the exaggeration by about half, saying 'bet' again with a smaller — but still noticeable — jaw drop.
Reduce one more time until the jaw drop feels natural but still clearly lower than your first attempt.
Compare 'bet' and 'bait' back to back, checking that 'bet' keeps the lower jaw position.
Record yourself saying both words and listen for a clear height difference.
Success check: You should feel your jaw and tongue settle in a clearly lower position for 'bet' than for 'bait', and the two words should sound distinctly different, not identical.
Exaggerated ɛ (overshoot)Jaw dropped much further than needed, tongue pressed low and flat, mouth very open — an intentional overshoot.Looks almost the same as the picture.
Target ɛ (dialed back)Jaw and tongue return to the normal, slightly-open mid-low position used in natural speech.
Overshoot the drop first so your ear and muscles learn the direction, then dial it back to normal.
Why this works. Overshooting the jaw-lowering and tongue-lowering gesture for ɛ beyond the normal target, then gradually dialing back to the correct degree, creates a clearer acoustic contrast (higher F1) against a habitual mid-front e substitute; research on acoustic exaggeration in phonetic training shows this strengthens categorical perception and production before the exaggeration is faded.
Japanese listeners successfully discriminate the acoustic properties of English /l/ and /r/ when presented with non-English contrasts, ruling out a universal hearing deficit.
The primary source of error is language-dependent categorization, where listeners map English sounds onto their existing L1 phonological categories (e.g., classifying both as liquids).
Performance improves significantly when the acoustic contrast between /l/ and /r/ is exaggerated or presented in contexts that highlight their distinctiveness.
Say 'book' with your habitual tense, tightly-rounded vowel and notice how your lips feel.
Now say 'book' again but barely round your lips at all and let your tongue go very relaxed — exaggerate in the opposite direction.
Repeat this under-rounded, very relaxed version three times, feeling how different it is from your first attempt.
Gradually add back a small amount of lip rounding until it feels like a light, natural rounding rather than none at all.
Say 'book' one more time at this new, lightly-rounded, relaxed setting.
Compare 'book' to 'boot' back to back, confirming 'book' uses much less lip tension.
Record both words and check that they sound clearly different, with 'book' shorter and looser.
Success check: You should feel your lips staying much looser for 'book' than your old habit, and 'book' versus 'boot' should sound clearly distinct, not like the same vowel.
Exaggerated ʊ (overshoot)Lips barely rounded at all, tongue very relaxed and low, jaw noticeably open — an intentional overshoot away from tense u.
Target ʊ (dialed back)Lips lightly rounded, tongue returns to its natural relaxed-but-not-extreme position.
First relax and under-round on purpose, then dial back to the natural, lightly rounded ʊ.
Why this works. Deliberately over-relaxing the tongue and under-rounding the lips beyond the natural ʊ target, then gradually reducing the exaggeration, pushes production away from the tense-u attractor and gives a clear articulatory landmark; exaggerated-contrast training strengthens categorical boundaries before fading into natural speech.
Japanese listeners successfully discriminate the acoustic properties of English /l/ and /r/ when presented with non-English contrasts, ruling out a universal hearing deficit.
The primary source of error is language-dependent categorization, where listeners map English sounds onto their existing L1 phonological categories (e.g., classifying both as liquids).
Performance improves significantly when the acoustic contrast between /l/ and /r/ is exaggerated or presented in contexts that highlight their distinctiveness.
Say 'bird' but stretch the vowel out for a full three seconds: 'buh-errrrrrd'.
Repeat this exaggerated version five times, keeping the curl steady the whole time.
Record yourself and confirm it sounds like one long, smooth curled sound, not two parts.
Now say 'bird' again with a normal, short vowel length, using that same tongue shape.
Compare recordings: the short version should feel like a compressed version of the long one.
Repeat with 'her', 'turn', and 'word', exaggerated then natural each time.
Finish by saying all four words at normal conversational speed.
Success check: Your normal-length 'er' should feel like a quick version of the long, exaggerated one — same tongue curl, just shorter — never split into two parts.
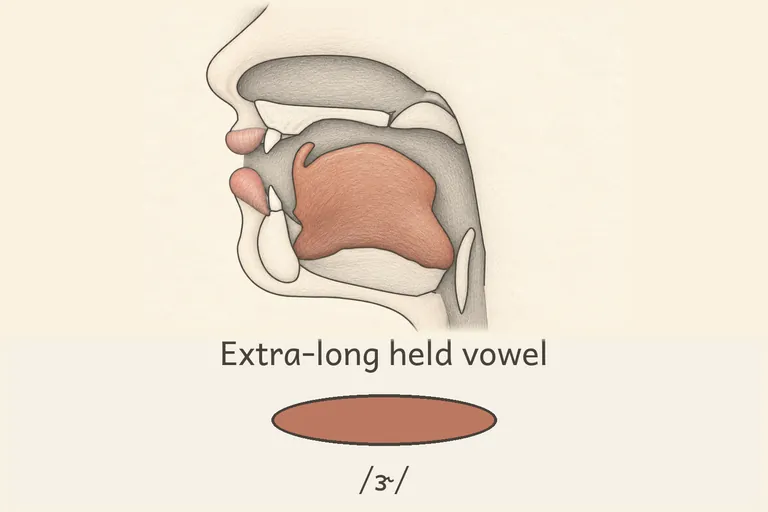
Exaggerated ɝAn extra-long, held 'errrrr' with the curl visibly sustained for several seconds.
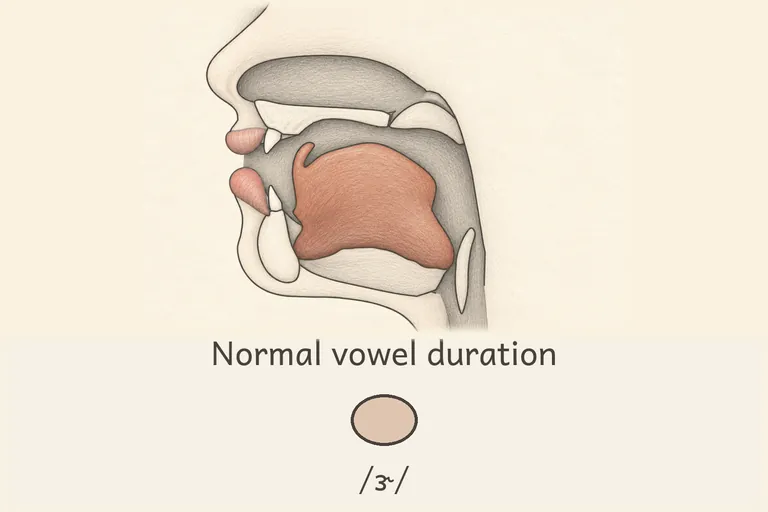
Natural ɝThe same curled shape, but shortened to normal vowel length within the word.
First stretch the curl out for seconds, then shrink it back down to normal word length.
Why this works. Stretching the rhotic vowel far beyond its natural duration exaggerates the temporal and spectral cues (sustained low F3) that mark it as a single fused nucleus rather than a vowel-plus-consonant sequence. Research on temporal acoustic exaggeration shows this kind of overshoot during early training accelerates native-like categorical perception and production, after which the exaggerated duration is dialed back to normal.
The HVPT-E group showed superior improvement in natural word identification compared to the standard HVPT group.
Temporal acoustic exaggeration promotes native-like categorical perception based on spectral cues in adult L2 learners.
Training with temporal exaggeration induces measurable changes in pre-attentive neural processing (MMN responses).
Borrow a Gesture You Already Know
consensus
proxy motor5 min★★☆🪞 mirror
Say the English word 'go' slowly and notice the lip shape right at the very start of the vowel, before it glides.
Freeze your lips in that exact starting shape — moderately rounded, not tightly pursed.
While keeping that lip shape frozen, raise the back of your tongue a little higher and tenser than it was for 'go'.
Add a slightly more closed jaw position while holding the frozen lip shape.
Say 'book' using this borrowed lip shape plus the adjusted tongue position.
Check in the mirror that your lips never pursed tightly forward the way they would for 'boot'.
Practice switching between the start of 'go' and 'book' five times to feel how the same lip gesture adapts to two different vowels.
Success check: You should feel the same moderate lip-rounding muscle activation you use at the start of 'go', just combined with a higher, tenser tongue position — and 'book' should sound short and relaxed, not like 'boot'.
Proxy gesture: starting position of 'go' (oʊ)Moderate lip rounding, mid-back tongue position, used as a motor starting point.
Adapted target: ʊSame moderate lip rounding, but tongue raised higher and tenser, jaw slightly more closed than the 'go' starting point.
Borrow the lip shape you already use at the start of 'go' and raise your tongue a bit higher and tenser to reach ʊ.
Why this works. The lip-rounding gesture for ʊ shares the same orbicularis oris activation used at the onset of the diphthong oʊ (as in 'go'), already automatized in the learner's motor repertoire; borrowing that familiar, moderate lip-rounding gesture rather than the tighter rounding of u, and pairing it with a shorter, laxer tongue position, gives learners a ready-made motor template to adapt.
Borrow the Yawn: From a Loose Jaw to the 'ih' Sound
generated
proxy motor5 min★★☆🪞 mirror
Start a small, relaxed half-yawn and notice how loose your jaw and tongue root feel.
Freeze that same loose feeling in your jaw before it turns into a full yawn.
While keeping that looseness, bring your tongue forward and slightly up, as if starting to say 'ee' but staying relaxed.
Say the word 'bit' right from that position.
Compare it to saying 'beat', noticing the jaw is looser and lower for 'bit'.
Repeat five times, going from the yawn feeling to the target sound, until it feels automatic.
Success check: You can trigger the relaxed jaw feeling on demand and land directly on a natural-sounding 'ih' without over-thinking your tongue position.
Proxy gesture: relaxed half-yawnBegin a small, relaxed yawn-like jaw drop, feeling the jaw and tongue root go loose.
Target: ɪKeep that same loose jaw feeling but bring the tongue forward and slightly up for the vowel in 'bit'.
Borrow the loose jaw feeling of a half-yawn, then bring the tongue forward to shape it into the vowel in 'bit'.
Why this works. The jaw-relaxation gesture needed for English ɪ is motorically similar to the slight jaw drop used in a relaxed half-yawn, which shares the same jaw-depressor and tongue-root relaxation muscle activity. Borrowing this already-automatic gesture as a proxy gives learners immediate access to the correct degree of openness without needing to learn a wholly new muscle pattern; they then narrow the tongue forward toward the front ɪ target.
Borrow the Yawn: From a Wide-Open Jaw to the 'a' Sound
generated
proxy motor5 min★★☆🪞 mirror
Start a wide, relaxed yawn and notice how far your jaw drops open.
Freeze that same wide-open feeling in your jaw before the yawn finishes.
While keeping that width, bring your tongue forward and slightly up, as if starting to say 'ah' but with the tongue front.
Say the word 'cat' right from that position.
Compare it to saying 'bed', noticing the jaw is much wider for 'cat'.
Repeat five times, going from the yawn feeling to the target sound and back, until it feels automatic.
Success check: You can trigger the wide-jaw feeling on demand and land directly on a natural-sounding 'a' without over-thinking your tongue position.
Proxy gesture: starting a yawnBegin a wide, relaxed yawn-like jaw drop, feeling the jaw open fully.
Target: æKeep that same wide jaw opening but bring the tongue forward and slightly up for the vowel in 'cat'.
Borrow the wide-open feeling of starting a yawn, then bring the tongue forward to shape it into the vowel in 'cat'.
Why this works. The wide jaw drop needed for æ is motorically similar to the initial jaw-opening gesture of a full yawn or an exaggerated 'ah', both driven by the same jaw-depressor muscles. Borrowing this already-automatic wide-open gesture as a proxy gives learners immediate access to the correct degree of aperture without new muscle learning; they then bring the tongue forward to the front æ target.
Say a word with a single-tap r, like Hungarian 'kar', and notice the quick, light touch your tongue tip makes against the ridge behind your teeth.
Do that same tap several times in isolation, without any vowel around it — just the tap sound alone.
Now say 'city', but instead of a full held t, replace the middle consonant with that same tap gesture.
Compare: say the tap alone, then immediately say 'ci-TAP-y' using the identical tongue motion.
Move on to 'butter', 'water', and 'little', using the same borrowed tap each time.
Check in the mirror that your tongue tip barely touches the ridge and bounces right off, just like it did for your r-tap.
Success check: The middle consonant in 'butter' feels exactly like your tap-r gesture, just without any trilling, and it sounds like a fast 'd' to a listener.
Tapped r (as in 'kar')Tongue tip makes one quick, light contact with the alveolar ridge, producing a brief tap.Looks almost the same as the picture.
English flap t (as in 'butter')An identical single tongue-tip tap against the alveolar ridge, borrowed directly from the r-tap gesture, with voicing continuing throughout.
The English flap t reuses the exact tongue-tip tap many learners already produce for a one-contact r.
Why this works. The American flap is articulatorily almost identical to a single alveolar tap, the same quick up-down tongue-tip gesture many learners already produce for a one-contact tapped r (as in Hungarian 'kar' or Spanish 'pero'). Borrowing this already-automatized tongue-tip tap and simply keeping voicing continuous, without adding a trill, lets learners access the flap through a familiar motor plan instead of building it from nothing.
Sit in front of a mirror and get ready to say 'bird' very slowly.
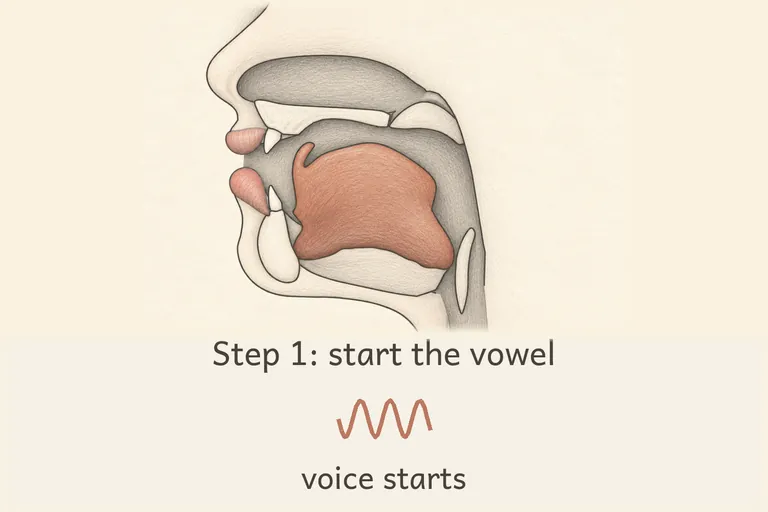
Step 1: as your voice starts, immediately lift and curl your tongue tip back (or bunch the middle upward) — don't wait.
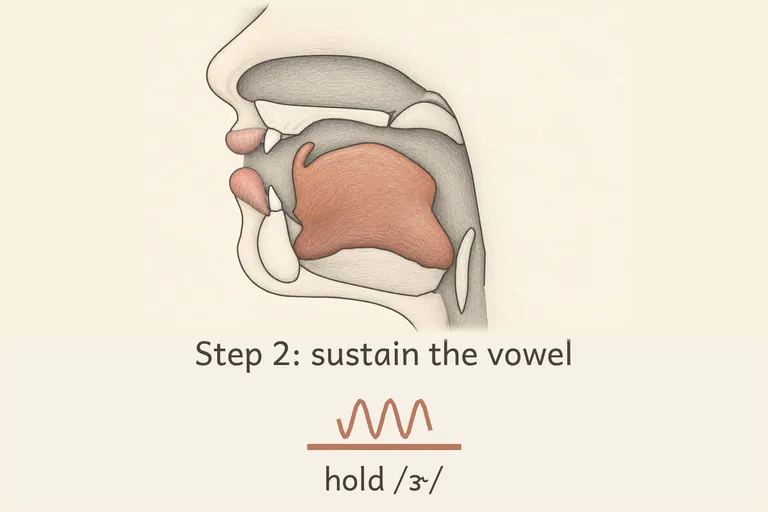
Step 2: freeze and hold that exact curled shape steady for two full seconds, watching in the mirror that it doesn't move.
Step 3: let the curl relax only at the very end, right before the final 'd' sound.
Say the whole word this way three times, checking the tongue never touches anything.
Now speed the three steps up gradually into one smooth 'er' sound.
Say 'bird', 'her', and 'turn' at normal speed using this same continuous shape.
Success check: The curl appears the instant the vowel starts and stays perfectly steady until the end — you should not be able to hear or feel two separate parts.
Step 1: startTongue begins already slightly curled or bunched as the voice starts.
Step 2: holdTongue holds the exact same curled shape steadily through the middle of the vowel.
Step 3: releaseThe curl relaxes only at the very end, as the sound finishes.
The curl starts immediately and stays put — it's one long held shape, not a shape added partway through.
Why this works. Slowing the vowel down and freezing it mid-production lets the learner verify, via mirror feedback, that the curled or bunched tongue posture is held steadily and continuously rather than added as an afterthought following a plain vowel — the exact segmentation error predicted by the L1's lack of a rhotic vowel category.
Kenesei, I., Vago, R.M., & Fenyvesi, A. (1998). Hungarian: Descriptive Grammar.
Build the Vowel in Slow Motion
sourced
slow motion steps6 min★★☆🪞 mirror
Look in a mirror and open your jaw as if starting to say 'bed', but freeze in that open position.
Check that your jaw is clearly more open than when you say 'bait'.
Hold that open position steady for two full seconds without moving your tongue.
Now add voice and say a flat, held vowel for two seconds, keeping the jaw position frozen.
Shorten the held vowel gradually over several repetitions until it's a normal-length syllable.
Say the full word 'bed' at normal speed, keeping the same jaw opening you practiced.
Record the final normal-speed version and compare it to a native model.
Success check: In the mirror, your jaw is visibly more open on 'bed' than on 'bait', and the vowel sound stays flat with no upward glide even at normal speed.
Step 1: openJaw dropped to a clearly open position, wider than for the eɪ vowel.
Step 2: hold flatTongue held steady at that lower height with no movement toward a higher position.
Open the jaw wider than for 'day', then hold the tongue flat and steady — don't let it glide upward.
Why this works. Slowing the vowel articulation into discrete steps — mouth-open position, tongue height check, steady hold — lets the learner consciously verify jaw opening and the absence of an off-glide before reintegrating the sound at normal speed, addressing the core articulatory error of insufficient lowering.
Non-lexical training materials produced greater pronunciation improvements for L2 learners compared to lexical (word-based) materials.
Masking noise during training hindered performance specifically for participants using non-lexical stimuli, but did not negatively affect those using words.
Training-induced gains in vowel production were more pronounced when vowels appeared in sentences than when elicited in isolated words.
Build ʊ in Slow Motion
consensus
slow motion steps6 min★★☆🪞 mirror
Say 'book' extremely slowly, freezing right after the 'b' sound before the vowel starts.
Hold your jaw in a slightly open position — a touch more open than you'd use for 'boot' — and freeze there.
Check in the mirror that your tongue is high and back but not pressed as far up as for 'boot'.
Round your lips only lightly, without pushing them forward into a tight circle.
Slowly release into the 'k' sound, keeping the vowel brief rather than drawn out.
Repeat the whole slow sequence three times, then speed it up gradually until it sounds like normal 'book'.
Compare your final fast version to 'boot' to confirm you haven't drifted back into the tense vowel.
Success check: You should feel a distinctly more relaxed jaw and lighter lip rounding for 'book' than for 'boot', and the vowel should sound short rather than drawn out.
Step 1: jaw setJaw drops slightly more than for tense u, mouth not fully closed.Looks almost the same as the picture.
Step 2: tongue heightTongue body rises high-back but stops short of the highest point used for u.
Step 3: lip roundingLips round only lightly, without pursing forward.
Build ʊ in three slow, frozen steps, then blend them into one smooth short vowel.
Why this works. Decomposing the ʊ gesture into discrete, held sub-stages (jaw position, tongue height, lip rounding) at slow speed lets learners isolate and correct each articulatory parameter separately before reassembling it at normal speed, a standard technique for installing a vowel target the L1 lacks.
Say 'this' with your tongue tip pushed far out between your teeth and an extra-loud, extra-long buzz.
Hold the exaggerated buzz for two full seconds before finishing the word.
Now say 'this' again with the tongue only slightly poking out, closer to natural speech, but keep the buzz clearly audible.
Compare: both versions should buzz, just with different amounts of visible tongue and length.
Repeat the big-then-small pattern with 'that', 'mother', and 'though'.
Finish with five natural-speed repetitions of all four words.
Success check: Your natural-speed ð should still show a small tongue-tip peek and a clear buzz — a smaller version of the exaggerated one, not a collapse into 'd' or 'z'.
ExaggeratedTongue pushed far out past the teeth, extra-loud, extra-long buzz.
NaturalTongue tip only slightly poking out, brief but clear buzz at normal speed.
Buzz it big first, then shrink the gesture down to natural size without losing the buzz.
Why this works. Overshooting both the tongue protrusion and the voiced buzz beyond what natural speech requires exaggerates the contrast between ð and the learner's habitual d/z substitutes, strengthening the new perceptual-motor category before it is dialed back to a natural, subtler articulation, consistent with findings that acoustic exaggeration during training improves category formation.
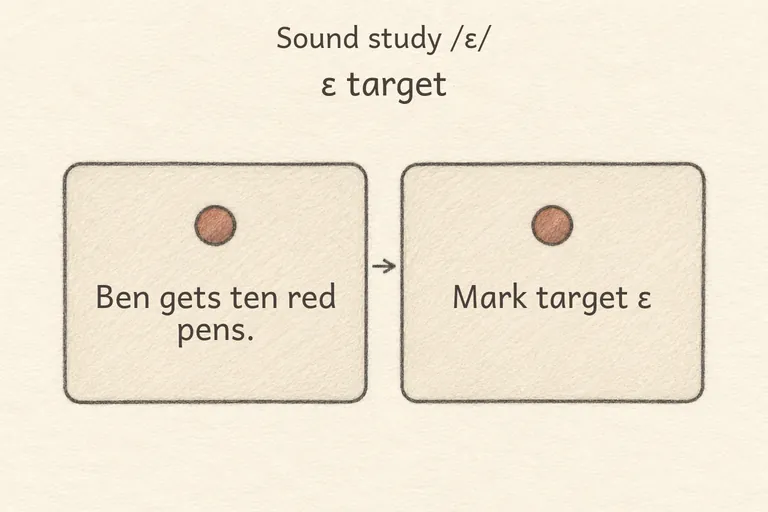
Read silently: 'I said the red-headed man gets many letters every week,' noting the underlined ɛ words.
Say the sentence slowly, dropping your jaw clearly on 'said', 'red', 'gets', 'many', and 'letters'.
Speed up to a natural conversational pace while keeping the same jaw opening on those words.
Record yourself reading the sentence at natural speed.
Listen back and mark any ɛ word that sounds too close to the eɪ vowel in 'day'.
Reread the sentence, exaggerating the jaw drop only on the marked words.
Success check: At natural speed, every targeted word ('said', 'red', 'gets', 'many', 'letters') has a clearly open, flat vowel with no upward glide.
ɛ targetJaw held open and flat through each underlined vowel in the sentence.
Keep your jaw equally open and flat on every underlined ɛ word as you read the sentence at normal speed.
Why this works. Embedding the target vowel in full carrier sentences rather than isolated words gives the learner practice maintaining the lower, glide-free articulation under natural coarticulatory and rhythmic pressure, which training research shows produces more pronounced, durable gains than isolated-word drills alone.
Non-lexical training materials produced greater pronunciation improvements for L2 learners compared to lexical (word-based) materials.
Masking noise during training hindered performance specifically for participants using non-lexical stimuli, but did not negatively affect those using words.
Training-induced gains in vowel production were more pronounced when vowels appeared in sentences than when elicited in isolated words.
Drill Sentence: All Three T's in One Breath
sourced
drill sentence5 min★★☆🎙 recorder
Read this sentence once silently: 'The waiter at the little water bar poured better butter for the writer's party.'
Mark every t: which ones start a stressed syllable (strong puff expected) and which ones fall between vowels (flap expected).
Say the sentence very slowly, exaggerating each t type as you go.
Record yourself saying it at a normal conversational speed.
Listen back and circle any t that still sounds like a uniform, fully-held stop everywhere.
Repeat the sentence five times, smoothing out the flapped t's until they disappear into quick taps.
Success check: You hear a clear puff on 'waiter' and 'water' at the start, but fast, almost d-like taps in the middle of 'little', 'water', 'better', and 'butter'.
Why this works. Drilling a sentence loaded with all three target allophones builds automaticity for context-dependent allophone selection under connected-speech demands, which isolated word practice does not train. Training-induced gains tend to be larger when target sounds are practiced embedded in sentences rather than elicited in isolation, since sentence context forces the learner to manage allophone switching at natural speed.
Non-lexical training materials produced greater pronunciation improvements for L2 learners compared to lexical (word-based) materials.
Masking noise during training hindered performance specifically for participants using non-lexical stimuli, but did not negatively affect those using words.
Training-induced gains in vowel production were more pronounced when vowels appeared in sentences than when elicited in isolated words.
Drill Sentence: Dad's Black Cat
sourced
drill sentence6 min★★☆🎙 recorder
Read this drill sentence silently: 'Dad's black cat sat on the flat mat and had a snack.'
Underline every word containing the target sound (Dad's, black, cat, sat, flat, mat, had, snack).
Say the sentence slowly, deliberately dropping your jaw wide for each underlined word.
Record yourself saying the sentence at a natural conversational speed.
Play it back and check that each underlined word sounds clearly wide and open, not like 'bed' or 'set'.
Repeat three times, gradually increasing speed while keeping the jaw drop consistent.
Success check: On playback, every underlined word keeps a wide-open quality even at natural speed, with none of them drifting toward 'e'.
Why this works. Embedding æ words in a connected sentence tests whether the wider jaw-opening gesture survives coarticulation with neighboring consonants and normal speaking rate, a stronger test of stable category formation than isolated word production; sentence-level practice has been shown to produce larger production gains than isolated words.
Both goodness ratings and intelligibility scores effectively captured improvements in vowel accuracy following pronunciation training.
The relationship between goodness and intelligibility varies by vowel; vowels like /æ/ and /ʌ/ depend more on goodness for listener identification than /i/ and /e/.
Some vowels received better mean intelligibility scores but poorer mean goodness ratings after training, indicating that high intelligibility does not always require high perceived quality.
Drill Sentence: Full of Good Books
consensus
drill sentence5 min★★☆🎙 recorder
Read this sentence silently first: 'The good cook put a full book on the wooden shelf.'
Mark every ʊ word in the sentence: good, cook, put, full, book, wooden.
Say the sentence slowly, relaxing your lips and tongue for each marked word.
Record yourself reading it at a slow, deliberate pace.
Play it back and check that none of the marked words sound like their tense-u twins.
Repeat the sentence three more times, gradually increasing to a natural conversational speed.
Do a final recording at normal speed and confirm all six target words still sound short and relaxed.
Success check: On your final recording at natural speed, all six ʊ words should sound clearly shorter and more relaxed than if you'd used the tense u vowel, and a listener should not confuse any of them with other words.
Why this works. Embedding multiple ʊ-words in a connected, meaningful sentence forces the learner to maintain the lax-vowel target under natural speech rate and coarticulation, bridging isolated-word accuracy and fluent, intelligible speech.
Read this sentence slowly first: 'The bird learned to turn toward the first word she heard.'
Underline every ɝ vowel (bird, learned, turn, first, word, heard).
Say the sentence very slowly, holding the curl steady through each underlined vowel.
Record yourself saying it at normal conversational speed.
Listen back for any underlined vowel that sounds like two parts instead of one smooth sound.
Repeat the sentence three more times, focusing only on the vowels you flagged.
Say the whole sentence five times at natural speed until every ɝ sounds fused and smooth.
Success check: At normal speed, every underlined vowel sounds like one continuous curled sound, with no separate tap or trill audible afterward.
Why this works. Dense repetition of ɝ in a natural sentence, across stressed monosyllables and multisyllabic words, pressure-tests whether the fused rhotic vowel gesture survives connected-speech demands, where learners most often revert to the L1 pattern of vowel-plus-separate-tap under time pressure.
Vowel contrast accuracy improved significantly from 62.5% to 78.3% in the targeted group, compared to only a 2.3% gain in the control group.
Stress accuracy rose from 60.8% to 76.4% for learners receiving targeted instruction, with large effect sizes (d=1.48 for vowels, d=0.92 for stress).
Qualitative data revealed that learners adopted durable strategies such as minimal pair drills and shadowing, leading to fewer real-world misunderstandings.
Drill Sentence: The Little Kid Did His Best
sourced
drill sentence6 min★★☆🎙 recorder
Read this drill sentence silently: 'The little kid did his best to fit six thick bricks in the tin bin.'
Underline every word containing the target sound (little, kid, did, his, fit, six, thick, bricks, tin, bin).
Say the sentence slowly, deliberately relaxing your tongue for each underlined word.
Record yourself saying the sentence at a natural conversational speed.
Play it back and check that each underlined word sounds relaxed and lax, not like a rushed 'ee'.
Repeat three times, gradually increasing speed while keeping the vowel quality steady.
Success check: On playback, every underlined word keeps a relaxed quality even at natural speed, with none of them drifting toward 'ee'.
Why this works. Embedding multiple ɪ target words in a connected sentence forces the learner to maintain the lax vowel quality under coarticulatory and prosodic pressure from surrounding segments and stress patterns, a more ecologically valid test of internalization than isolated word production; sentence-level practice has been shown to yield larger production gains than isolated words.
Both goodness ratings and intelligibility scores effectively captured improvements in vowel accuracy following pronunciation training.
The relationship between goodness and intelligibility varies by vowel; vowels like /æ/ and /ʌ/ depend more on goodness for listener identification than /i/ and /e/.
Some vowels received better mean intelligibility scores but poorer mean goodness ratings after training, indicating that high intelligibility does not always require high perceived quality.
Drill Sentences for V
generated
drill sentence10 min★★☆🎙 recorder
Read this sentence slowly, marking every 'v': 'Victor loves to drive his van to visit seven villages.'
Before each 'v', pause briefly and check that your lower lip is rising toward your upper teeth, not closing both lips.
Record yourself reading the sentence at a natural pace.
Play it back and listen to each 'v' — does it buzz continuously, or does it sound like a 'b'?
Mark any words where the 'v' sounded like 'b' and repeat just those words five times each.
Read the full sentence again at normal speed, aiming for every 'v' to buzz clearly.
Success check: On playback, every 'v' in the sentence has a continuous buzzing quality and none of them sound like 'b'.
Why this works. Embedding the target sound in varied, meaningful sentence contexts promotes transfer from isolated articulatory control to connected speech, where coarticulation with neighboring vowels and consonants can pull the gesture back toward the L1 bilabial habit if not actively monitored.
Read this sentence slowly, underlining every 'uh' vowel: 'The young monkey loves to run and jump for fun in the sun.'
Before each underlined word, briefly check your lips are flat and your tongue is centered, not rounded or pulled back.
Record yourself reading the sentence at a natural pace.
Play it back and listen to each underlined vowel — does it sound bright and central, or does it drift toward 'ah' or 'o'?
Mark any words that drifted and repeat just those words five times, exaggerating the flat lips.
Read the full sentence again at normal speed, keeping every 'uh' vowel unrounded and central.
Success check: On playback, every underlined vowel in the sentence sounds short, bright, and central, with no rounding creeping in on any of them.
Why this works. Drilling the target vowel inside full sentences, rather than isolated words, trains the learner to maintain the unrounded, centralized tongue posture under the coarticulatory pressure of surrounding consonants and vowels, where the risk of reverting to the rounded, backed L1 substitute is highest.
Non-lexical training materials produced greater pronunciation improvements for L2 learners compared to lexical (word-based) materials.
Masking noise during training hindered performance specifically for participants using non-lexical stimuli, but did not negatively affect those using words.
Training-induced gains in vowel production were more pronounced when vowels appeared in sentences than when elicited in isolated words.
Exaggerate First, Then Dial It Back
sourced
exaggeration7 min★★☆🎙 recorder
Say 'top' with a huge, cartoonish puff of air after the t — almost like you're blowing out a candle.
Say 'butter' with an extremely long, loose, floppy tap in the middle — let the tongue bounce almost in slow motion.
Say 'button', holding the glottal stop for a full second before releasing into the n.
Record all three exaggerated versions.
Now say the same three words at about 70% of that exaggeration — still clearly puffed, tapped, and glottalized, but closer to normal speed.
Finally, say them at natural conversational speed, keeping just a trace of each distinct quality.
Compare your natural-speed recording to the exaggerated one and confirm the contrast is still audible, just subtler.
Success check: Even at normal speed, a listener can still tell 'top' has a puff, 'butter' has a tap, and 'button' has a stop-nasal release — the exaggeration training left behind a real, audible trace.
Exaggerated training stageA dramatically long aspiration burst on 'top', an extremely slow floppy tap on 'butter', and a held one-second glottal stop on 'button'.Looks almost the same as the picture.
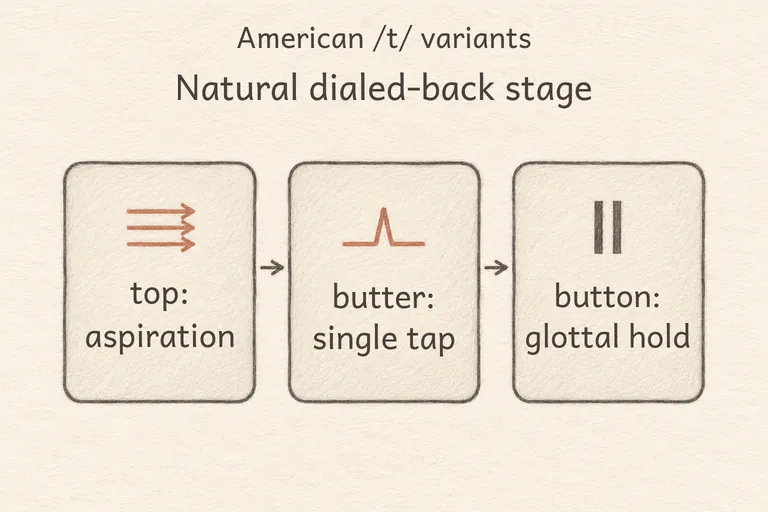
Natural dialed-back stageThe same three contrasts at normal conversational speed: a brief puff, a fast light tap, and a quick glottal stop before the nasal release.
Starting with cartoonish exaggeration of each t-type makes the subtler natural-speed version easier to keep distinct.
Why this works. Overshooting each allophone's defining cue (burst length, tap looseness, closure duration) before fading toward natural speed strengthens category learning more than practicing at normal speed from the start, since exaggerated training has been shown to induce more native-like categorical perception and leaves a durable trace even once the exaggeration is dialed back.
The HVPT-E group showed superior improvement in natural word identification compared to the standard HVPT group.
Temporal acoustic exaggeration promotes native-like categorical perception based on spectral cues in adult L2 learners.
Training with temporal exaggeration induces measurable changes in pre-attentive neural processing (MMN responses).
Exaggerate Then Normalize: The Relaxed 'ih' Sound
sourced
exaggeration7 min★★☆🪞 mirror🎙 recorder
Say 'bit' with an exaggerated, almost cartoonish jaw drop, holding the relaxed vowel for twice its normal length.
Repeat this exaggerated version five times, focusing on how different it feels from a tense 'beat'.
Gradually shorten the exaggerated hold by about half, keeping the same relaxed quality.
Shorten it again until the duration feels close to normal conversational speed.
Record yourself at this more natural speed and compare it to a native model.
If it starts drifting back toward 'beat', return to the exaggerated version for a few reps before trying again.
Success check: You can move smoothly from an exaggerated, obviously relaxed 'bit' down to a natural-speed 'bit' without losing the relaxed vowel quality.
Exaggerated ɪJaw dropped further than normal, tongue clearly relaxed and held for an extra beat, almost cartoonish.Looks almost the same as the picture.
Natural ɪSame relaxed quality but with normal jaw opening and duration, blended smoothly into connected speech.
Practice an exaggerated, extra-relaxed 'bit' first, then dial the same looseness back to a natural speaking size.
Why this works. Temporarily overshooting the jaw drop and tongue relaxation for ɪ, holding the lax quality longer than natural speech requires, exaggerates the acoustic distance from the L1 substitute vowel and sharpens the learner's own kinesthetic and auditory feedback loop. The exaggerated form is then dialed back toward natural speech once the new category is stable, consistent with research showing that acoustic and temporal exaggeration during training improves categorical perception and generalizes to natural production.
Japanese listeners successfully discriminate the acoustic properties of English /l/ and /r/ when presented with non-English contrasts, ruling out a universal hearing deficit.
The primary source of error is language-dependent categorization, where listeners map English sounds onto their existing L1 phonological categories (e.g., classifying both as liquids).
Performance improves significantly when the acoustic contrast between /l/ and /r/ is exaggerated or presented in contexts that highlight their distinctiveness.
Exaggerate Then Normalize: The Wide-Open 'a' Sound
sourced
exaggeration7 min★★☆🪞 mirror🎙 recorder
Say 'cat' with an exaggerated, almost cartoonish wide jaw drop, holding the vowel for twice its normal length.
Repeat this exaggerated version five times, focusing on how different it feels from 'bed'.
Gradually shorten the exaggerated hold by about half, keeping the same wide quality.
Shorten it again until the duration feels close to normal conversational speed.
Record yourself at this more natural speed and compare it to a native model.
If it starts drifting back toward the 'e' sound, return to the exaggerated version for a few reps before trying again.
Success check: You can move smoothly from an exaggerated, obviously wide 'cat' down to a natural-speed 'cat' without losing the wide-open vowel quality.
Exaggerated æJaw dropped further than normal, almost like a wide yawn, held for an extra beat.Looks almost the same as the picture.
Natural æSame wide quality but with normal jaw opening and duration, blended smoothly into connected speech.
Practice an exaggerated, extra-wide 'cat' first, then dial the same openness back to a natural speaking size.
Why this works. Temporarily overshooting the jaw drop for æ, dropping the jaw further than natural speech requires and holding the open quality longer, exaggerates the acoustic distance from the L1 ɛ substitute and sharpens the learner's own kinesthetic and auditory feedback. The exaggerated form is then dialed back toward natural speech, consistent with research showing acoustic and temporal exaggeration during training improves categorical perception and generalizes to natural production.
Japanese listeners successfully discriminate the acoustic properties of English /l/ and /r/ when presented with non-English contrasts, ruling out a universal hearing deficit.
The primary source of error is language-dependent categorization, where listeners map English sounds onto their existing L1 phonological categories (e.g., classifying both as liquids).
Performance improves significantly when the acoustic contrast between /l/ and /r/ is exaggerated or presented in contexts that highlight their distinctiveness.
Exaggerate V, Then Dial It Back
sourced
exaggeration8 min★★☆🎙 recorder
Say 'vvvvvvan' holding the initial 'v' buzz for a full three seconds, deliberately too long and too loud.
Record this exaggerated version and listen for a clear, sustained buzz with no trace of a lip-closing pop.
Repeat with 'vvvvvvery' and 'vvvvvvote', again holding the 'v' far longer than normal.
Now say the same words with the 'v' at only half that length, still clearly buzzing but closer to normal speed.
Finally, say the words at a natural conversational pace, keeping the buzz but shortening it further.
Compare your natural-pace recording to the exaggerated one and confirm the buzzing quality survived the shrink.
Success check: Your natural-speed 'v' still has an audible, brief buzz (not a pop), and you can clearly recall the exaggerated version as a reference if the sound slips back toward 'b'.
Why this works. Temporarily overshooting the contrast — holding the labiodental contact and voiced buzz far longer and more forcefully than natural speech requires — widens the perceptual and motor distance from the L1 bilabial substitute, making the category boundary unmistakable before the learner dials the gesture back down to a natural, brief duration; this overshoot-then-fade strategy mirrors temporal exaggeration techniques shown to sharpen categorical perception in L2 training.
Say 'cuhhhhp' with your lips pulled as flat and wide as possible and the vowel held far too long, exaggerating the lack of rounding.
Record this exaggerated version and confirm it sounds nothing like the rounded Hungarian 'a'.
Repeat with 'luhhhhck' and 'luhhhhve', again holding the exaggerated flat vowel.
Now say the same words with only half that exaggeration, keeping the vowel shorter and the lip-flattening less extreme.
Finally, say the words at a natural conversational pace, keeping the lips unrounded but the vowel brief and natural.
Compare your natural-pace recording to the exaggerated one and confirm the vowel still sounds bright and central, not rounded.
Success check: Your natural-speed 'cup' still sounds clearly unrounded and central, and you can recall the exaggerated flat-lip version as a reference anytime the vowel starts drifting back toward the rounded Hungarian 'a'.
Why this works. Deliberately over-centralizing and over-flattening the vowel — pushing the tongue further forward and the lips flatter than natural English requires — creates a large, unmistakable perceptual and motor distance from the rounded, backed Hungarian substitute, making the category boundary vivid before the gesture is dialed back to a natural articulation; this overshoot-then-fade approach mirrors exaggeration-based training shown to sharpen categorical vowel perception in adult L2 learners.
Both goodness ratings and intelligibility scores effectively captured improvements in vowel accuracy following pronunciation training.
The relationship between goodness and intelligibility varies by vowel; vowels like /æ/ and /ʌ/ depend more on goodness for listener identification than /i/ and /e/.
Some vowels received better mean intelligibility scores but poorer mean goodness ratings after training, indicating that high intelligibility does not always require high perceived quality.
Feel the Difference: Bad vs. Bed
sourced
minimal pair produce12 min★★☆🪞 mirror🎙 recorder
Stand in front of a mirror and say 'bed', noticing how far your jaw opens.
Now say 'bad', deliberately dropping your jaw noticeably wider than for 'bed'.
Alternate bed-bad-bed-bad five times, watching your jaw in the mirror each time.
Record yourself saying five more pairs (man/men, sat/set, pan/pen).
Play back the recording and judge whether 'bad' clearly sounds more open than 'bed'.
Repeat, exaggerating the jaw drop slightly if the two words still sound too similar.
Success check: On playback, 'bad' sounds clearly more open and lower than 'bed', and a listener could reliably tell them apart.
Producing ɛ (bed)Jaw moderately open, tongue mid-low and front.Looks almost the same as the picture.
Producing æ (bad)Jaw dropped noticeably wider, tongue lower and slightly forward, almost like starting a yawn.
Alternate 'bed' and 'bad' in the mirror, watching your jaw drop clearly wider for 'bad'.
Why this works. Alternating production of æ/ɛ minimal pairs forces an active, larger jaw-opening gesture for æ immediately next to the smaller opening for ɛ, making the required range of jaw movement explicit and measurable rather than left as an unconscious habit that keeps reusing the smaller L1-based opening. Because listener judgments of /æ/ depend heavily on perceived vowel quality rather than just recognizability, deliberately exaggerating the jaw-opening contrast in practice targets the dimension listeners actually rely on.
Both goodness ratings and intelligibility scores effectively captured improvements in vowel accuracy following pronunciation training.
The relationship between goodness and intelligibility varies by vowel; vowels like /æ/ and /ʌ/ depend more on goodness for listener identification than /i/ and /e/.
Some vowels received better mean intelligibility scores but poorer mean goodness ratings after training, indicating that high intelligibility does not always require high perceived quality.
Feel the Difference: Bit vs. Beat
consensus
minimal pair produce12 min★★☆🪞 mirror🎙 recorder
Stand in front of a mirror and say 'beat' slowly, noticing your tongue is high and tense and your jaw is barely open.
Now say 'bit', deliberately relaxing your tongue and letting your jaw drop slightly more.
Alternate beat-bit-beat-bit five times, exaggerating the jaw and tension difference each time.
Record yourself saying five more minimal pairs (sit/seat, fill/feel, chip/cheap).
Play back the recording and check whether 'bit' sounds clearly different from 'beat', not just shorter.
Repeat the set, aiming for a clear quality difference every time, not just a speed difference.
Success check: When you record yourself, 'bit' sounds relaxed and lower, not like a fast 'beat', and a listener could tell the two words apart from quality alone.
Producing i (beat)Tongue high and tense, lips slightly spread, jaw nearly closed.Looks almost the same as the picture.
Producing ɪ (bit)Tongue drops slightly and relaxes, jaw opens a touch more, muscles loosen.
Alternate between 'beat' and 'bit', feeling the tongue relax and the jaw open a little more for 'bit'.
Why this works. Alternating production of ɪ/i minimal pairs forces an active switch in tongue height and muscular tension between two adjacent articulations, strengthening the motor-perceptual link built during listening training and preventing a durational-only substitution where the tense vowel is merely shortened.
Say the noun 'OBject', stressing the first syllable and keeping its vowel full and clear.
Now say the verb 'obJECT', stressing the second syllable and letting the first syllable collapse into a quick, relaxed schwa.
Alternate OBject-obJECT five times, exaggerating the difference in vowel clarity between the two forms.
Record yourself saying three more pairs (CONvict/conVICT, PERmit/perMIT, PROgress/proGRESS).
Play back the recording and check that the unstressed syllable sounds noticeably shorter and less clear than the stressed one.
Repeat, relaxing the unstressed syllable a little more each time if it still sounds too full.
Success check: On playback, the unstressed syllable in each pair sounds clearly quicker and more neutral than the stressed one, not equally full.
Full vowel (stressed)Mouth shapes a clear, full vowel with normal jaw and lip movement on the stressed syllable.
Reduced schwa (unstressed)Mouth barely moves, jaw stays relaxed and central, producing a quick, neutral 'uh' on the unstressed syllable.
Practice saying 'OBject' and 'obJECT' back to back, letting the unstressed syllable go soft and quick.
Why this works. Producing stress-shifting pairs forces the learner to actively alternate between a full, clearly articulated vowel and a reduced, effortless schwa within the same word root, making the otherwise invisible reduction process an explicit, controllable articulatory target rather than a habit overridden by full-vowel pronunciation carried over from a language without reduction.
Ladefoged, P., & Johnson, K. (2015). A Course in Phonetics.
Find Schwa Through a Relaxed Sigh
consensus
proxy motor5 min★★☆🪞 mirror
Let your jaw hang loose and sigh out gently, as if you're a little tired: 'huh...'
Notice that your tongue isn't reaching forward, back, up, or down — it's just sitting in the middle of your mouth.
Shorten that same relaxed sigh into a quick, tiny sound: 'uh'.
Attach that same tiny relaxed 'uh' onto the end of 'sofa': so-fuh.
Do the same for 'about': uh-BOUT, keeping the first syllable as light as your sigh.
Check in the mirror that your lips stay unrounded and your jaw barely moves for that syllable.
Success check: The unstressed syllable should feel as effortless as your sigh — no lip rounding, no jaw drop, no tongue reaching.
Shaped vowelLips rounded or spread, jaw dropped for a full vowel like 'ah' or 'oh'.
Resting schwaJaw loosely hanging, lips neutral, tongue centered, as in a relaxed sigh.
Schwa is just your resting 'sigh' position, shrunk into a syllable.
Why this works. Schwa is produced with the tongue and jaw in their neutral resting position, the same posture the vocal tract adopts during a relaxed exhale or a hesitation sound like 'huh'. Anchoring schwa to this already-automatic neutral posture recruits the same jaw and tongue-body muscles at rest, bypassing the learner's habit of shaping a full, spelled-out vowel for every syllable.
Ladefoged, P. & Johnson, K. (2015). A Course in Phonetics.
Overdo the Reduction, Then Ease Back
sourced
exaggeration5 min★★☆🎙 recorder
Say 'about' extremely reduced, almost dropping the first syllable entirely: 'BOUT'.
Say it again, adding back just a whisper of a vowel before 'bout': 'uh-BOUT', kept very short.
Compare the two versions and notice the small but real difference.
Repeat the overshoot-then-ease pattern with 'sofa': first 'SO-f' with almost no final vowel, then 'SO-fuh' with a faint schwa.
Do the same with 'banana': first 'nan-uh' dropping the first syllable, then 'buh-NAN-uh' with a light first syllable.
Settle on the middle version — reduced but not silent — as your final natural pronunciation.
Success check: The final version should sound clearly reduced compared to a full vowel, but still contain a faint, quick vowel sound rather than disappearing completely.
OvershootUnstressed syllable almost disappears, mouth barely moving.Looks almost the same as the picture.
Natural targetA small but audible schwa reappears, still clearly reduced compared to the stressed syllables.
Squeeze the unstressed syllable almost to nothing, then let a little of it back in.
Why this works. Because Hungarian learners default to full vowel quality on every syllable, briefly overshooting the reduction — nearly dropping the unstressed syllable entirely — recalibrates the target so that a properly reduced but still audible schwa feels comparatively 'full' once dialed back; exaggerated training expands the perceptual-motor window before settling on the natural, subtler target.
Read this sentence slowly: 'This is the mother of that other brother, though he's leaving.'
Exaggerate the tongue-tip-between-teeth gesture on every ð word, keeping your voice buzzing.
Record yourself reading it slowly and carefully.
Play it back and mark any ð that sounded like a hard 'd' or a 'z' hiss instead.
Repeat the sentence three more times, gradually speeding up while watching your tongue in the mirror.
Read it once more at natural conversational speed.
Success check: Every ð should show a brief tongue-tip appearance with a continuous buzz, even when you're speaking at normal speed.
Marked sentenceA practice sentence with every ð word underlined and a small vibration icon marking the buzz cue.
Find every ð in the sentence and keep the tongue-tip buzz going each time, even at speed.
Why this works. Because ð appears constantly in high-frequency function words, embedding it in a full sentence forces repeated, rapid re-execution of the tongue-protrusion-plus-buzz gesture amid the coarticulatory pressure of neighboring sounds, testing whether the new gesture has become automatic rather than a careful, isolated performance.
Non-lexical training materials produced greater pronunciation improvements for L2 learners compared to lexical (word-based) materials.
Masking noise during training hindered performance specifically for participants using non-lexical stimuli, but did not negatively affect those using words.
Training-induced gains in vowel production were more pronounced when vowels appeared in sentences than when elicited in isolated words.
Practice θ in a Full Sentence
sourced
drill sentence6 min★★☆🪞 mirror🎙 recorder
Read this sentence slowly: 'I think the three thin brothers took a bath on Thursday.'
Go word by word, exaggerating the tongue-tip-between-teeth gesture on every θ word.
Record yourself reading it at a slow, careful pace.
Play it back and mark any θ that sounded like 't' or 's'.
Repeat the sentence three more times, speeding up slightly each time while keeping the tongue protrusion visible in the mirror.
Read it once more at a natural conversational speed.
Success check: Every θ in the sentence should show a brief tongue-tip appearance in the mirror and produce a soft hiss, even at natural speed.
Marked sentenceA practice sentence with every θ word underlined and its tongue-protrusion cue marked with a small tooth icon.
Find every θ in the sentence and protrude the tongue tip each time, even at speed.
Why this works. Embedding θ in full sentences with multiple instances forces repeated, rapid re-execution of the tongue-protrusion gesture amid the coarticulatory pressure of neighboring sounds, which is the real test of whether the new gesture has become automatic rather than a careful, isolated performance.
Non-lexical training materials produced greater pronunciation improvements for L2 learners compared to lexical (word-based) materials.
Masking noise during training hindered performance specifically for participants using non-lexical stimuli, but did not negatively affect those using words.
Training-induced gains in vowel production were more pronounced when vowels appeared in sentences than when elicited in isolated words.
Produce the Pair Contrast
sourced
minimal pair produce7 min★★☆🎙 recorder
Say 'bait' first, feeling your tongue glide slightly upward.
Immediately say 'bet', dropping your jaw more and keeping the tongue flat with no glide.
Repeat the 'bait–bet' pair five times, exaggerating the jaw drop on 'bet'.
Record yourself saying all four pairs: bait/bet, wait/wet, late/let, mate/met.
Play back the recording and check that each ɛ word sounds clearly lower and flatter than its eɪ partner.
Redo any pair that sounds too similar, dropping your jaw even further on the ɛ word.
Success check: A listener (or you, on playback) can clearly tell which word in each pair is which, based on jaw height and the presence or absence of a glide.
Produce baitTongue rising slightly from mid to high during the vowel.
Produce betTongue dropping and staying low and flat through the vowel.
Drop your jaw more and keep the tongue flat for 'bet'; let it glide upward for 'bait'.
Why this works. Producing the two members of each minimal pair back-to-back forces the learner to actively control tongue height and glide presence as the sole distinguishing gesture, converting the perceptual contrast established in listening practice into a reliable, repeatable articulatory routine.
Both goodness ratings and intelligibility scores effectively captured improvements in vowel accuracy following pronunciation training.
The relationship between goodness and intelligibility varies by vowel; vowels like /æ/ and /ʌ/ depend more on goodness for listener identification than /i/ and /e/.
Some vowels received better mean intelligibility scores but poorer mean goodness ratings after training, indicating that high intelligibility does not always require high perceived quality.
Produce the Three American T's
sourced
minimal pair produce8 min★★☆🎙 recorder🪞 mirror
Say 'top' out loud, pushing a strong puff of air right after the t — hold a tissue in front of your mouth and watch it flutter.
Say 'stop' the same way, but keep the t crisp with almost no puff of air, since it follows s.
Say 'butter' slowly, then speed up until the middle t turns into a quick, light tap of the tongue tip — almost a fast American 'd'.
Say 'button', and instead of releasing the t normally, stop the air completely and release it through your nose into the n.
Record yourself saying all four words in a row: top, stop, butter, button.
Play it back and check for four distinct sounds: strong puff, no puff, quick tap, swallowed stop.
Repeat five times, exaggerating each version before settling into a natural speed.
Success check: Your recording shows four clearly different t's — a puffy one, a crisp one, a fast tap, and a nasal-released one — not four identical dental stops.
Aspirated TTongue tip meets the alveolar ridge, full stop, strong burst of air released right as the vowel begins.
Flapped TTongue tip taps the alveolar ridge once, briefly, with voicing continuing through — no full stop or burst.
Same tongue placement, two very different releases: a held aspirated stop versus one quick voiced tap.
Why this works. Moves from perception to production, training the learner to generate three distinct allophones of /t/ on cue. Tracking both how correct (goodness) and how clear (intelligibility) a produced sound is gives a more complete picture of progress than accuracy judgments alone, which is especially useful here since a flapped t can sound 'wrong' in isolation yet be perfectly intelligible in context.
Both goodness ratings and intelligibility scores effectively captured improvements in vowel accuracy following pronunciation training.
The relationship between goodness and intelligibility varies by vowel; vowels like /æ/ and /ʌ/ depend more on goodness for listener identification than /i/ and /e/.
Some vowels received better mean intelligibility scores but poorer mean goodness ratings after training, indicating that high intelligibility does not always require high perceived quality.
Push Your 'd' Forward Into ð
consensus
proxy motor5 min★★☆🪞 mirror
Say a crisp 'd' and notice your tongue tip touching just behind your top front teeth, with your voice buzzing.
Say 'd' again, letting the tongue tip slide a bit further forward, to the back of your top teeth.
Push just a little more so the tongue tip peeks out between your teeth.
Instead of stopping the airflow completely like 'd' does, let the air and voice buzz continuously over the tongue tip.
Practice the transition: 'd... d... voiced-th... voiced-th...', feeling the tongue creep forward each time.
Attach the final voiced position to the word 'this', starting from the 'd' spot and sliding forward each rep.
Success check: You should feel the tongue slide forward from your familiar 'd' spot, ending with the tip lightly between your teeth and a continuous buzz instead of a quick stop.
Familiar 'd'Tongue tip touching the alveolar ridge, voice buzzing but air fully stopped.
Target ðTongue tip slid slightly forward between the teeth, voice buzzing continuously with airflow, no stop.
Take your 'd' and just push the tongue tip a little further forward, letting the buzz keep flowing.
Why this works. ð recruits the same tongue-tip fronting and vocal-fold-vibration muscles already used for the native voiced alveolar stop 'd'; sliding the familiar 'd' tongue-tip gesture a few millimeters further forward past the alveolar ridge, and releasing it as a continuous buzz instead of a stop, repurposes an existing motor-voicing program instead of building an entirely new one.
Celce-Murcia, M., Brinton, D., & Goodwin, J. (2010). Teaching Pronunciation.
Push Your 't' Forward Into θ
consensus
proxy motor5 min★★☆🪞 mirror
Say a crisp 't' and notice where your tongue tip touches — right behind your top front teeth.
Say 't' again, but let the tongue tip slide a little further forward, to the back of your top teeth.
Push just a bit further so the tongue tip peeks out between your teeth.
Instead of stopping the air completely like 't' does, let a thin stream of air hiss continuously over the tongue tip.
Practice the transition: 't... t... th... th...', feeling the tongue creep forward each time.
Attach the final 'th' position to the word 'think', starting each rep from the 't' spot and sliding forward.
Success check: You should feel the tongue-tip motion as a small forward slide from your familiar 't' spot, ending with the tip lightly between your teeth and a steady hiss instead of a stopped sound.
Familiar 't'Tongue tip touching the alveolar ridge just behind the upper teeth, air stopped completely.
Target θTongue tip slid slightly forward, poking between the teeth, air flowing continuously as a hiss.
Take your 't' and just push the tongue tip a little further forward.
Why this works. θ recruits the same tongue-tip fronting muscles (genioglossus anterior and tongue-tip flexors) already used for the native alveolar stop 't'; by taking the familiar 't' tongue-tip gesture and sliding it a few millimeters further forward past the alveolar ridge to the teeth, learners repurpose an existing motor program instead of building an entirely new one.
Celce-Murcia, M., Brinton, D., & Goodwin, J. (2010). Teaching Pronunciation.
Reduce the Weak Beats in a Sentence
sourced
drill sentence6 min★★☆🪞 mirror🎙 recorder
Read this sentence slowly: 'The banana is on the table about an hour ago.'
Mark which syllables carry the main stress: ba-NA-na, TA-ble, a-BOUT, HOUR.
Say the stressed syllables fully and clearly, giving them extra length and a small pitch bump.
Rush through every other syllable, letting your jaw and tongue go slack so they collapse into a quick 'uh'.
Record yourself saying the sentence at natural conversational speed.
Play it back and check that unstressed syllables sound short and blurry, not crisp.
Repeat five times, gradually speeding up while keeping the stressed syllables clear.
Success check: You should hear a strong up-and-down rhythm, with unstressed syllables sounding almost swallowed compared to the clear, elongated stressed ones.
Stress markedA practice sentence shown with stressed syllables in bold capital letters and unstressed syllables shown smaller and shaded gray.
Mark the strong beats first, then let every other syllable shrink toward a quick 'uh'.
Why this works. Repeating full sentences forces the learner to reduce unstressed vowels to schwa in real time while maintaining sentence-level stress and timing, which is the actual skill needed for natural rhythm; drilling isolated words does not train the automatic reduction that happens across word boundaries and in function words in connected speech.
Non-lexical training materials produced greater pronunciation improvements for L2 learners compared to lexical (word-based) materials.
Masking noise during training hindered performance specifically for participants using non-lexical stimuli, but did not negatively affect those using words.
Training-induced gains in vowel production were more pronounced when vowels appeared in sentences than when elicited in isolated words.
Say it and check: one fused 'er'
consensus
minimal pair produce8 min★★☆🎙 recorder
Say 'bud' and notice your tongue stays low and flat the whole time.
Now say 'bird', starting the tongue curl at the very beginning of the vowel, not after it.
Record yourself saying: bird/bud, third/thud.
Play it back and ask: does 'bird' sound like one smooth, curled sound, or like a vowel plus a separate tap?
If you hear two parts, start the curl earlier, right as your voice begins.
Re-record until 'bird' sounds like a single continuous sound from start to finish.
Move to the next pair only after two clean recordings in a row.
Success check: On playback, the rhotic vowel should sound like one smooth, curled sound the whole way through, not a plain vowel followed by a separate tap.
Wrong: two partsA plain vowel is followed by a brief separate tongue-tip tap.
Right: one fused soundTongue rises into the curled or bunched shape at the very start of the vowel and holds it the whole way through.
Curl the tongue from the very first instant of the vowel and hold it — don't add the curl afterward.
Why this works. Production practice on bird/bud-type pairs targets the core error pattern of producing a separate vowel-plus-tap sequence instead of one fused rhotic nucleus. Recording lets the learner check for a single continuous sound rather than two audible segments, since this segmentation error is not detectable through kinesthetic feedback alone for someone whose L1 has no rhotic vowel.
Stand in front of a mirror and say 'fool', watching your lips push forward and round tightly.
Now say 'full', consciously relaxing your lips to only a light rounding and keeping the vowel short.
Alternate 'full, fool, full, fool' five times, exaggerating the lip-tension difference each time.
Record yourself saying both words and play it back immediately.
Check whether 'full' sounds noticeably shorter and looser than 'fool'.
Repeat with 'pull/pool' and 'look/Luke', applying the same relaxed-lips technique to the ʊ word.
If a listener or app can't tell your pairs apart, slow down and relax your lips even more for the ʊ word.
Success check: A listener (or playback) should be able to tell 'full' from 'fool' reliably, and you should feel noticeably less lip tension and a shorter vowel on the ʊ word.
Producing ʊ (full)Lips lightly rounded, tongue relaxed and slightly lower, shorter vowel duration.Looks almost the same as the picture.
Producing u (fool)Lips tightly rounded and pushed forward, tongue tense and high, longer vowel duration.
Aim for a shorter, looser vowel in 'full' than the tight, long 'oo' in 'fool'.
Why this works. Active production of the same minimal pairs forces control of tongue height/tension and lip rounding to keep the contrast audible; immediate self-recording and playback gives the auditory feedback loop associated with vowel-accuracy gains in L2 training.
Both goodness ratings and intelligibility scores effectively captured improvements in vowel accuracy following pronunciation training.
The relationship between goodness and intelligibility varies by vowel; vowels like /æ/ and /ʌ/ depend more on goodness for listener identification than /i/ and /e/.
Some vowels received better mean intelligibility scores but poorer mean goodness ratings after training, indicating that high intelligibility does not always require high perceived quality.
Say It Right: Producing English V
sourced
minimal pair produce10 min★★☆🪞 mirror🎙 recorder
Stand in front of a mirror and say 'ffff' first, noticing your lower lip touching your upper teeth.
Keep that exact lip-teeth position, then turn on your voice to make a buzzing 'vvvv' sound without moving your lips.
Say 'van' slowly, holding the 'v' for two full seconds before releasing into the vowel.
Check in the mirror that your lips never fully close together during the 'v'.
Record yourself saying 'van, vote, very' and compare to the model audio.
Repeat until your lip-teeth contact is visible and consistent in every repetition.
Success check: In your recording, the 'v' sound hums continuously for about a quarter second before the vowel, and your mirror shows the lower lip against the teeth with the upper lip never closing against it.
Your old habitBoth lips come together, same as for 'b'.
Target shapeLower lip lifts and rests lightly against the edge of the upper front teeth; upper lip stays relaxed and open.
Watch your mouth in the mirror: for 'v', only the lower lip touches the teeth — the upper lip never meets the lower lip.
Why this works. Production practice on true minimal pairs forces the learner to commit to one articulatory gesture per trial rather than an ambiguous bilabial-labiodental blend. Recording and self-comparison against a model gives feedback on visible lower-lip-to-teeth contact and continuous frication, the two cues American listeners rely on most to separate /v/ from /b/.
Substitution occurs when learners replace L2 phonemes with the closest available sound in their native language, often causing meaning changes (e.g., Spanish /v/ becoming /b/).
Omission involves dropping sounds that do not exist in the learner's L1 or are difficult to articulate due to L1 constraints.
Insertion (epenthesis) happens when learners add vowels to break up consonant clusters that their native language does not support.
Wells, J.C. (1982). Accents of English.
Say It Right: Producing English ʌ
sourced
minimal pair produce10 min★★☆🪞 mirror🎙 recorder
Look in a mirror and say the Hungarian word 'kor', noticing your rounded lips.
Now relax your lips completely flat, as if about to say 'ah', and keep your tongue from pulling backward.
Say 'cup' slowly, checking in the mirror that your lips never round at any point during the vowel.
Say the pair 'cup' then 'cop' back to back, exaggerating the lip difference between them at first.
Record yourself saying 'cup, luck, love, done' and check each vowel sounds short, central, and unrounded.
Repeat until your lips stay visibly flat and relaxed on every single word.
Success check: In the mirror, your lips show zero rounding during the vowel in 'cup', and your recording sounds noticeably brighter and more central than your old 'cop'-like version.
Old habit (ɒ)Lips visibly rounded and pushed slightly forward, tongue pulled back.
Target (ʌ)Lips completely relaxed and unrounded, tongue resting in the center of the mouth.
Watch your lips: for English 'uh' in 'cup', they must stay flat and relaxed — no rounding at all.
Why this works. Producing true minimal pairs forces an either/or commitment between the central unrounded target and the back rounded L1 substitute; visual mirror feedback on lip shape combined with recorded playback gives the two feedback channels most useful for correcting a vowel-quality error, consistent with research showing vowel training benefits from feedback across both isolated and connected-speech contexts.
Both goodness ratings and intelligibility scores effectively captured improvements in vowel accuracy following pronunciation training.
The relationship between goodness and intelligibility varies by vowel; vowels like /æ/ and /ʌ/ depend more on goodness for listener identification than /i/ and /e/.
Some vowels received better mean intelligibility scores but poorer mean goodness ratings after training, indicating that high intelligibility does not always require high perceived quality.
Non-lexical training materials produced greater pronunciation improvements for L2 learners compared to lexical (word-based) materials.
Masking noise during training hindered performance specifically for participants using non-lexical stimuli, but did not negatively affect those using words.
Training-induced gains in vowel production were more pronounced when vowels appeared in sentences than when elicited in isolated words.
Say the Pairs, Feel the Buzz
sourced
minimal pair produce6 min★★☆🪞 mirror🎙 recorder
In the mirror, say 'then', watching your tongue tip rest lightly between your teeth while your voice buzzes.
Now say 'den' right after, pulling the tongue back to make a full stop behind your teeth.
Alternate: then-den, then-den, five times, exaggerating the tongue position switch.
Repeat with though-dough and breathe-breed.
Record all three pairs.
Play back and confirm the ð words show a continuous buzz and visible tongue-tip peek, while the d/z words don't.
Success check: You should feel a steady vibration on your tongue tip for ð words, versus a quick stop or a hiss from further back on the d/z words.
Saying 'then'Tongue tip briefly visible between the teeth, continuous buzz.
Saying 'den'Tongue tip pulled back, quick stop, no protrusion visible.
Watch your tongue tip pop out and buzz only on the ð word, not on its d/z twin.
Why this works. Producing minimal pairs back-to-back forces a rapid articulatory switch between the tongue-protruded continuous buzz of ð and the retracted stop or fricative (d/z) already automatized in Hungarian, strengthening the motor contrast needed to keep the two categories separate in running speech.
Japanese listeners successfully discriminate the acoustic properties of English /l/ and /r/ when presented with non-English contrasts, ruling out a universal hearing deficit.
The primary source of error is language-dependent categorization, where listeners map English sounds onto their existing L1 phonological categories (e.g., classifying both as liquids).
Performance improves significantly when the acoustic contrast between /l/ and /r/ is exaggerated or presented in contexts that highlight their distinctiveness.
Say the Pairs, Feel the Difference
sourced
minimal pair produce6 min★★☆🪞 mirror🎙 recorder
Look in the mirror and say 'think', watching your tongue tip poke out between your teeth.
Now say 'sink' right after, pulling your tongue back behind your teeth for the 's'.
Alternate: think-sink, think-sink, five times, exaggerating the tongue position change each time.
Repeat with thank-tank, bath-bat, and mouth-mouse.
Record yourself producing all four pairs.
Play it back and check that the θ words show visible tongue protrusion in the mirror and a soft hiss on playback, while the t/s words don't.
Success check: Your tongue tip should briefly appear between your teeth only on the θ words, with a soft, breathy hiss rather than a sharp 's' or hard tap.
Saying 'think'Tongue tip briefly visible between the teeth.
Saying 'sink'Tongue tip pulled back, no protrusion visible.
Watch your tongue tip pop out only on the θ word, not on its t/s twin.
Why this works. Producing minimal pairs back-to-back forces a rapid articulatory switch between the protruded-tongue fricative θ and the retracted stop or fricative (t/s) already automatized in Hungarian, strengthening the motor contrast needed to keep the two categories separate in running speech.
Japanese listeners successfully discriminate the acoustic properties of English /l/ and /r/ when presented with non-English contrasts, ruling out a universal hearing deficit.
The primary source of error is language-dependent categorization, where listeners map English sounds onto their existing L1 phonological categories (e.g., classifying both as liquids).
Performance improves significantly when the acoustic contrast between /l/ and /r/ is exaggerated or presented in contexts that highlight their distinctiveness.
Slow-Motion Glide from 'e' to the Wide-Open 'a' Sound
consensus
slow motion steps8 min★★☆🪞 mirror
Say 'bed' and freeze, noticing your jaw's current moderate opening.
Slowly drop your jaw further, moving in slow motion over about two seconds.
Stop once your jaw feels clearly wider than for 'bed' and hold that position.
Say the word 'bad' starting directly from that wide-open held position.
Repeat the three-step glide (moderate opening, slow widen, hold) five times.
Now do it at normal speed, keeping the same wide target for the vowel.
Success check: You can feel your jaw open noticeably wider between the starting position and the held target, and 'bad' no longer feels like a slightly-tweaked 'bed'.
Step 1: Start at ɛJaw at its usual moderately-open position, as in 'bed'.
Step 2: Drop furtherSlowly widen the jaw opening well past the ɛ position, in slow motion.
Step 3: Hold æSettle into the wide-open target and hold for a full second before releasing into the word.
Glide in slow motion from the 'e' jaw position down to the wider 'a' position, holding the open target before speaking.
Why this works. Decomposing the æ gesture into staged jaw-opening steps lets learners consciously monitor and control the degree of aperture, normally achieved too quickly for conscious correction, converting a categorical, all-or-nothing habit into a gradable motor skill.
Slow-Motion Glide from Full Vowel to Neutral Schwa
consensus
slow motion steps8 min★★☆🪞 mirror
Say the word 'photograph' slowly, noticing the full, clear vowel in the first syllable.
Now say the related word 'photography', and freeze on the second syllable, which reduces to a quick, neutral sound.
Slowly move your tongue and jaw from a fuller vowel position toward the neutral center, in slow motion over two seconds.
Stop once your mouth feels like it is barely moving and hold that relaxed, central position.
Say the unstressed syllable directly from that held, neutral position.
Repeat the slow-motion glide (full vowel, slow relax, hold) five times, then try the whole word at normal speed.
Success check: You can feel your jaw and tongue movement shrink noticeably between the full stressed vowel and the held, neutral schwa, and unstressed syllables sound quick and light rather than fully pronounced.
Step 1: Full vowelArticulate the stressed syllable's full vowel with normal jaw and tongue movement, e.g., the first vowel in 'photograph'.
Step 2: Relax toward centerSlowly let the jaw and tongue return toward a neutral, mid-central resting position, in slow motion.
Step 3: Hold schwaSettle into the minimal, relaxed schwa position and hold it briefly before finishing the word.
Glide in slow motion from a full vowel down to a barely-there schwa, feeling the jaw and tongue relax toward the center.
Why this works. Breaking the transition from a full stressed vowel to a reduced schwa into slow-motion stages lets learners consciously monitor the loss of jaw movement, lip rounding, and tongue displacement that occurs during reduction, converting an automatic but L1-absent process into a controllable articulatory routine.
Ladefoged, P., & Johnson, K. (2015). A Course in Phonetics.
Slow-Motion Glide from Tense 'ee' to Relaxed 'ih'
consensus
slow motion steps8 min★★☆🪞 mirror
Say a long, tense 'eeee' and freeze, noticing the high, tight tongue position.
Slowly let your tongue sink and your jaw relax, moving in slow motion for about two seconds.
Stop at the point where your tongue feels clearly lower and looser, and hold that position.
Say the word 'bit' starting directly from that relaxed, held position.
Repeat the three-step glide (tense 'ee', slow relax, hold) five times.
Now do it at normal speed, keeping the same relaxed target for the final vowel.
Success check: You can feel your tongue and jaw relax measurably between the starting 'ee' and the final held vowel, and 'bit' no longer feels like a rushed 'beat'.
Step 1: Start at iTongue high, tense, near the roof of the mouth, as if starting to say 'ee'.
Step 2: Relax and lowerSlowly let the tongue body sink and the muscles go slack, jaw easing open.
Step 3: Hold ɪSettle into the relaxed, slightly lower target position and hold it for a full second.
Move through three slow stages from tense 'ee' down to relaxed 'ih', feeling the tongue loosen at each step.
Why this works. Breaking articulation into slow-motion stages (starting tongue position, gradual lowering, final hold) lets learners consciously monitor tongue height and jaw aperture, movements normally executed too quickly to control, converting an unconscious durational substitution into a deliberate qualitative gesture.
Step 1 – Place: put your tongue tip lightly on the alveolar ridge, just behind your top front teeth, not touching the teeth themselves.
Step 2 – Tap, don't hold: instead of stopping the airflow completely, let your tongue tip bounce off the ridge in one quick, light flick.
Step 3 – Stay voiced: keep your vocal cords vibrating the whole time, so the tap sounds more like a fast 'd' than a 't'.
Practice the tap alone, over and over, outside of any word: da-da-da-da with a very light touch.
Insert it into 'city': say 'ci', then the tap, then 'y', very slowly at first.
Gradually speed up 'city', 'butter', 'water', 'little' until the tap happens automatically at full speed.
Success check: At full speed, 'butter' sounds smooth and fast, with the middle consonant barely touching — closer to 'budder' than to a crisp, held 't'.
Step 1: PlaceTongue tip rests lightly on the alveolar ridge, not touching the teeth.
Step 2: TapTongue tip bounces off the ridge in one quick, light flick rather than holding a full stop.
Step 3: Stay voicedVocal cords keep vibrating throughout the tap, giving it a d-like quality.
Building the American flap step by step: place, tap, and stay voiced throughout.
Why this works. Breaking the flap gesture into discrete motor steps (place, tap, voice) lets learners isolate the single ballistic tongue-tip movement that produces the alveolar tap, separating it from the full stop-plus-aspiration gesture typically substituted at every position.
Start with your lips relaxed and slightly open, not touching.
Very slowly, raise only your lower lip until it lightly touches the bottom edge of your upper front teeth.
Hold that contact for two seconds without making any sound.
Now add your voice, creating a steady buzzing hum while keeping the same lip-teeth contact.
Slowly release the lip and let the hum flow directly into a vowel, as in 'vvv-an'.
Repeat the four steps three times, gradually speeding up until it feels like one smooth motion.
Try the full-speed word 'van' and check it still has the buzz, not a pop.
Success check: You can feel the lower lip touch only the upper teeth (never the upper lip) at slow speed, and the buzzing sound appears before any sense of a 'popped' release.
Step 1: RestLips relaxed and slightly parted, as in a neutral position.
Step 2: LiftLower lip rises slowly until it just grazes the bottom edge of the upper front teeth.
Step 3: VoiceWith contact held, the vocal folds start vibrating, producing a steady buzz before the lips separate into the vowel.
Slow down the gesture: rest, lift the lower lip to the teeth, then add the buzz — no lip-to-lip closing at any step.
Why this works. Breaking the gesture into slow-motion stages isolates the single articulatory parameter that differs from the L1 habit — lip rounding/closure versus labiodental contact — letting the learner consciously rehearse the unfamiliar motor sequence before reintegrating it into normal-speed speech, a standard technique for installing a new place of articulation.
Start by saying your Hungarian 'a' sound and freeze, noticing your rounded lips and backed tongue.
Keeping the tongue still, slowly relax and flatten your lips until they are completely neutral.
Now, without rounding again, slide your tongue slowly from the back of your mouth toward the center.
Hold this new central, unrounded position for two seconds and notice how different it feels from the start.
Add a short burst of voice to turn the position into the vowel sound of 'cup'.
Repeat the three-step sequence five times, then try saying 'cup' at normal speed.
Success check: At slow speed, you can clearly feel two separate movements — lips unrounding, then tongue moving forward to center — and the final sound matches the short, bright vowel in 'cup', not the darker Hungarian 'a'.
Step 1: Start positionBegin from the rounded, backed Hungarian /ɒ/ shape.
Step 2: UnroundSlowly relax and flatten the lips, keeping the tongue in place.
Step 3: CentralizeGently slide the tongue forward from the back of the mouth toward the center, arriving at the relaxed target vowel.
Two separate moves: first flatten the lips, then glide the tongue from back to center.
Why this works. Slowing the vowel gesture into discrete stages lets the learner consciously decouple two L1-linked parameters — tongue backing and lip rounding — that are bundled together in Hungarian /ɒ/ but must both be independently neutralized to reach central, unrounded English /ʌ/, a decoupling that is difficult to achieve at normal speaking speed.
Say 'think' with your tongue tip pushed way out past your teeth, further than feels natural.
Exaggerate the hiss too, holding it for a full two seconds.
Now say 'think' again with the tongue only slightly poking out, closer to normal speech.
Compare: both versions should have a clear hiss, just with different amounts of visible tongue.
Repeat this big-then-small pattern with 'three', 'bath', and 'mouth'.
Finish with five natural-speed repetitions of all four words.
Success check: Your natural-speed θ should still show a small but clearly visible tongue-tip peek and a soft hiss — a scaled-down version of the exaggerated one, not a collapse back into 't' or 's'.
ExaggeratedTongue pushed far out past the teeth, held for a long hiss.
NaturalTongue tip only slightly poking out, brief hiss at normal speed.
Go big first, then shrink the gesture down to natural size without losing the hiss.
Why this works. Overshooting the tongue protrusion — pushing it further out than natural speech requires — exaggerates the acoustic and proprioceptive contrast between θ and the learner's habitual t/s substitutes; research on acoustic exaggeration in training shows this strengthens the new perceptual-motor category before the gesture is dialed back to a subtler, natural-speed protrusion.
Make a short growling sound, feeling your tongue pull back and bunch upward.
Freeze your tongue in that exact bunched position.
Add your voice and stretch the sound out into a long 'errrrr', without moving your tongue.
Check in the mirror that your tongue never touches the roof of your mouth during the stretch.
Shorten the stretched sound down to a normal vowel length, as in 'her' or 'bird'.
Say 'bird', 'her', and 'word', starting each one from that same growl-based tongue shape.
Repeat five times until the shape feels automatic without needing the growl first.
Success check: The vowel should feel like a shortened, voiced version of your growl — same tongue shape, no contact, held steadily through the whole vowel.
Growl heldTongue body pulled back and bunched, mouth relaxed, as in a low growl.
Stretched into a vowelSame held posture, now voiced and stretched into a long 'errrr' sound with no consonant closure.
Hold your growl shape, add your voice, and stretch it out — that stretched growl is your 'er' vowel.
Why this works. The bunched-tongue posture for ɝ shares its muscle group (tongue-dorsum retraction via styloglossus/palatoglossus) with the growl gesture used as a proxy for consonantal r. Extending the held growl posture into a vowel-length, voiced sound lets learners reuse an already-trained non-speech motor pattern to reach the fused rhotic vowel target, rather than building the gesture from a plain vowel outward.
Say 'cat' and notice how wide open your jaw drops for that vowel.
Hold that same open jaw position without moving it.
From that position, raise only your tongue body slightly higher, without closing the jaw.
Add voice and say 'bed' using this adjusted tongue height with the same open jaw.
Alternate saying 'cat' then 'bed' five times, feeling the small tongue-height change while the jaw stays equally open.
Record both words and compare your 'bed' vowel to a native model's ɛ.
Success check: Your jaw stays about as open for 'bed' as it is for 'cat', but the vowel sound is clearly higher and more ɛ-like than æ.
Proxy: æ (cat)Jaw very open, tongue low and front, already a familiar target.
Target: ɛ (bed)Same jaw opening as æ, but tongue body raised slightly higher.
Start from the jaw-open feeling of 'cat' (æ), then raise your tongue just slightly to land on 'bed' (ɛ).
Why this works. English ɛ shares its jaw-lowering gesture with the vowel æ (as in 'cat'), which Spanish-background learners typically already produce with an adequately open jaw; by starting from the æ jaw position and raising the tongue body slightly while keeping the same open jaw, the learner recruits the same jaw-depressor muscle activity already mastered for æ as a proxy motor target for ɛ.
Hualde, J.I. (2005). The Sounds of Spanish. Cambridge University Press.
Use Your 'E' to Find 'ʌ'
consensus
proxy motor8 min★★☆🪞 mirror
Say the Hungarian vowel 'e' (as in 'kert') and notice your jaw height and relaxed lips.
Keeping your jaw at that exact same height, let your tongue ease back just slightly, away from the front of your mouth.
Keep your lips completely relaxed and unrounded the whole time — do not let them move.
Say 'cup' using this adjusted tongue position and jaw height.
Alternate between your Hungarian 'e' and this new sound several times, feeling only the small backward tongue shift.
Check in the mirror that your jaw doesn't drop lower or your lips don't round during the shift.
Success check: You can feel your jaw stay at the same height as for Hungarian 'e', with only a small, controlled backward tongue movement, and your lips remain completely flat throughout.
Known gesture: Hungarian ɛMid-low tongue height, slightly fronted, lips neutral — as in Hungarian 'e'.Looks almost the same as the picture.
New target: ʌSame mid-low tongue height, but tongue eases back very slightly toward the center of the mouth, lips staying neutral and relaxed.
Start from your 'e' sound's jaw height, then let the tongue ease back just slightly to the center for English 'uh'.
Why this works. English /ʌ/ shares its mid-low jaw-opening and tongue-height target with Hungarian /ɛ/ (as in 'e'); by starting from the already-automatized /ɛ/ tongue-height gesture and easing the tongue very slightly back toward center while keeping the lips neutral (removing any fronting bias), the learner reuses an existing jaw/tongue-height routine from the same muscle group and only needs to adjust the front-back parameter, rather than learning an entirely new tongue height.
Say a long 'ffffff', the same sound as in Spanish 'fácil', and notice exactly where your lower lip touches your upper teeth.
Keep your lips frozen in that exact position.
Without moving your lips, turn on your voice so the sound becomes a buzzing 'vvvvv' instead of the hissy 'ffff'.
Alternate ffff-vvvv-ffff-vvvv several times, changing only the voicing, not the lip position.
Once the switch feels automatic, attach it to a vowel: 'ffff...vvvv-an' to produce 'van'.
Check in the mirror that your lip position truly does not move between the f and v versions.
Success check: You can flip between 'ffff' and 'vvvv' by only turning your voice on and off, with zero visible change in lip position.
Known gesture: FLower lip against upper teeth, voiceless airflow, as in Spanish 'fácil'.
New target: VIdentical lip-teeth position, but the vocal folds now vibrate, adding a buzz.
You already know this mouth shape from /f/ — just switch on your voice to get /v/.
Why this works. English /v/ shares its exact place of articulation (labiodental) with /f/, a voiceless labiodental fricative that already exists in the Spanish sound inventory (e.g., 'fácil'). Using /f/ as a proxy motor template lets the learner borrow an already-automatized lip-teeth gesture from the orbicularis oris / lower-lip musculature, then simply add vocal fold vibration to convert it into /v/, bypassing the need to learn a brand-new articulatory placement.
Substitution occurs when learners replace L2 phonemes with the closest available sound in their native language, often causing meaning changes (e.g., Spanish /v/ becoming /b/).
Omission involves dropping sounds that do not exist in the learner's L1 or are difficult to articulate due to L1 constraints.
Insertion (epenthesis) happens when learners add vowels to break up consonant clusters that their native language does not support.